

Atlassian teams run the strictest version control in the industry and apply it to everything except product context. Code lives in Bitbucket with branches, reviews, and history. The PRD it came from lives in Confluence, where the "last edited" stamp is the whole audit trail. The Jira ticket links to the page, and an AI agent reading any of the three starts from zero every time.
Product Map now connects all three Atlassian tools. Bitbucket holds the context repository the agents read and write. Jira and Confluence feed it through one connector.
This walkthrough follows every screen in that setup across four phases: create the project and link Bitbucket, connect Jira and Confluence, draft a PRD from a Confluence page, then file a Jira ticket and push the updated backlog and spec back to the repo.
Keep product context in Git
A Confluence page is a fine place to write a PRD. It is a poor place for an agent to read one, for three reasons.
- Every read is a fetch. An agent reading Confluence needs a token, a scope, a page ID, and an API round trip on every run. An agent reading a repo opens a file.
- Nothing is reviewed. A Confluence edit is live the moment someone hits Publish. A repo change lands as a diff with a reviewer's name on it, or not at all.
- History is locked in the UI. Bitbucket gives you
git logandgit blamefor every line of product context. Confluence page history exists, and no agent reads it.
Product Map's answer is one .productmap folder in your Bitbucket repository, holding one-pagers, strategy, PRDs, and research as plain Markdown, structured by the TASK framework. Every agent reads from that folder before it drafts anything. Every change it proposes lands as a commit or a pull request you review first, the shared workspace discipline engineering already runs on.
Confluence and Jira don't go away. They become inputs and outputs. The PRD starts in Confluence, gets pulled into the repo as context, and the ticket goes out to Jira. The repository sits in the middle as the copy every agent trusts.
Why agents run faster on a Git-backed context layer
The cost shows up on every run, not once. Before an agent drafts a spec or scores a backlog, it loads context: what the product is, who it serves, what's in flight. Where that context lives sets the bill.
The Markdown benchmark puts numbers on it. The same product overview costs 649 tokens as Markdown and 12,715 as JSON, the shape APIs hand back. Delivery path matters as much as format: pulling one Notion page live through its MCP server took around 18 seconds and roughly 6,200 model tokens in tool calls and block conversion. Once the same page sat in the repo as Markdown, the read needed no auth handshake and no tool calls. The agent opened the file and paid for the text alone.
Fetch the Confluence page once, accept it into the repository as Markdown, and every later agent run reads it at file prices instead of API prices.
That is the whole argument for the loop in section 3. The connector does the expensive fetch one time, under your review. The repository serves the cheap read forever after, to Product Map agents and to Claude Code or Cursor alike, because all of them speak Git natively and none speaks Confluence without setup.
1. Create a project and link it with a Git repo
A project is the container Product Map binds to one Bitbucket repository. This phase covers onboarding, seeding context, and the seven screens that take you from a new project to Bitbucket Connected.
Complete onboarding and add a project
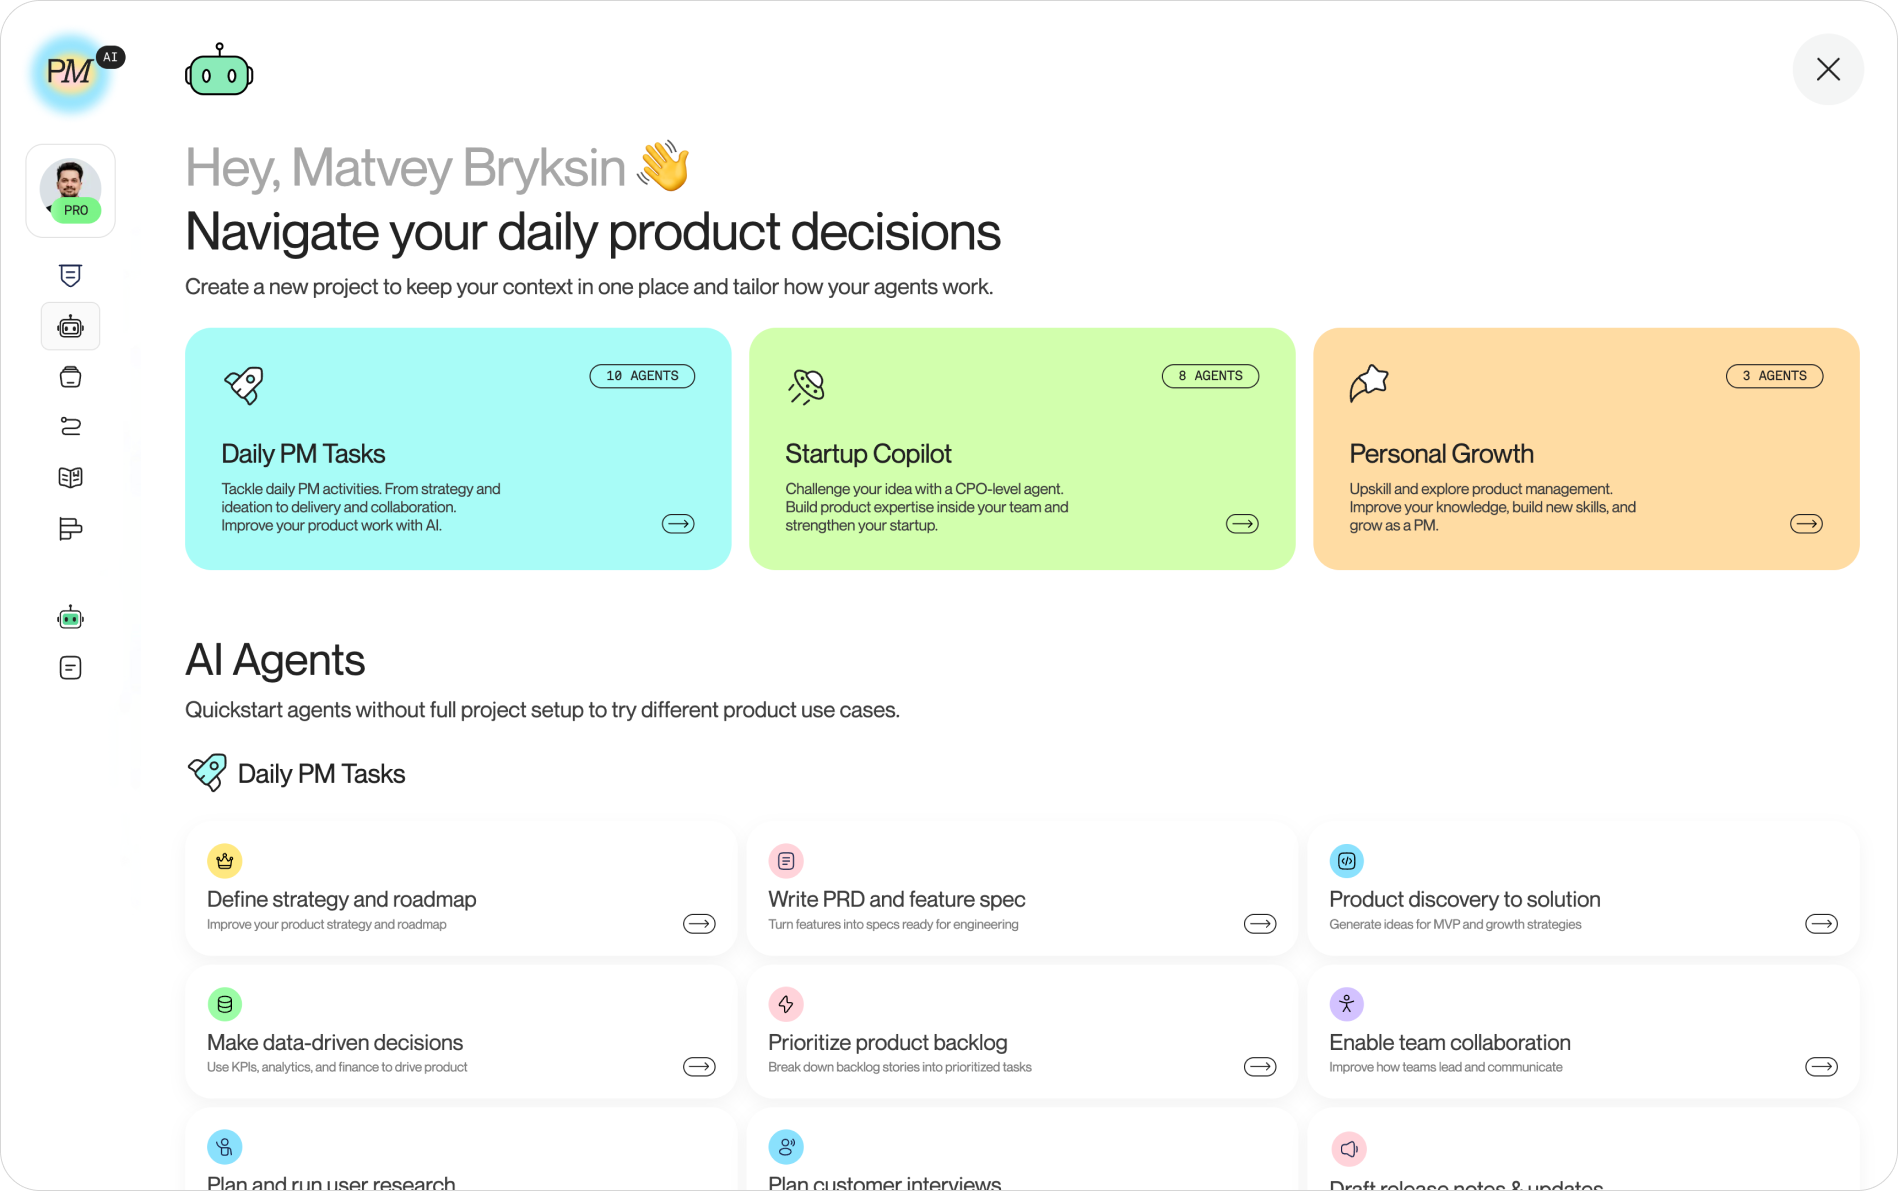
Every new Product Map account lands on the quick-start screen. It lays out three workspace types: Daily PM Tasks, Startup Copilot, and Personal Growth, each bundling a different set of agents. Below them sits a flat list of every agent available without a full project setup.
Pick the workspace that matches what you're building context for, then click Add project in the left sidebar. Name it after the product itself. One product gets one project, not one project per team or initiative.
Seed project context
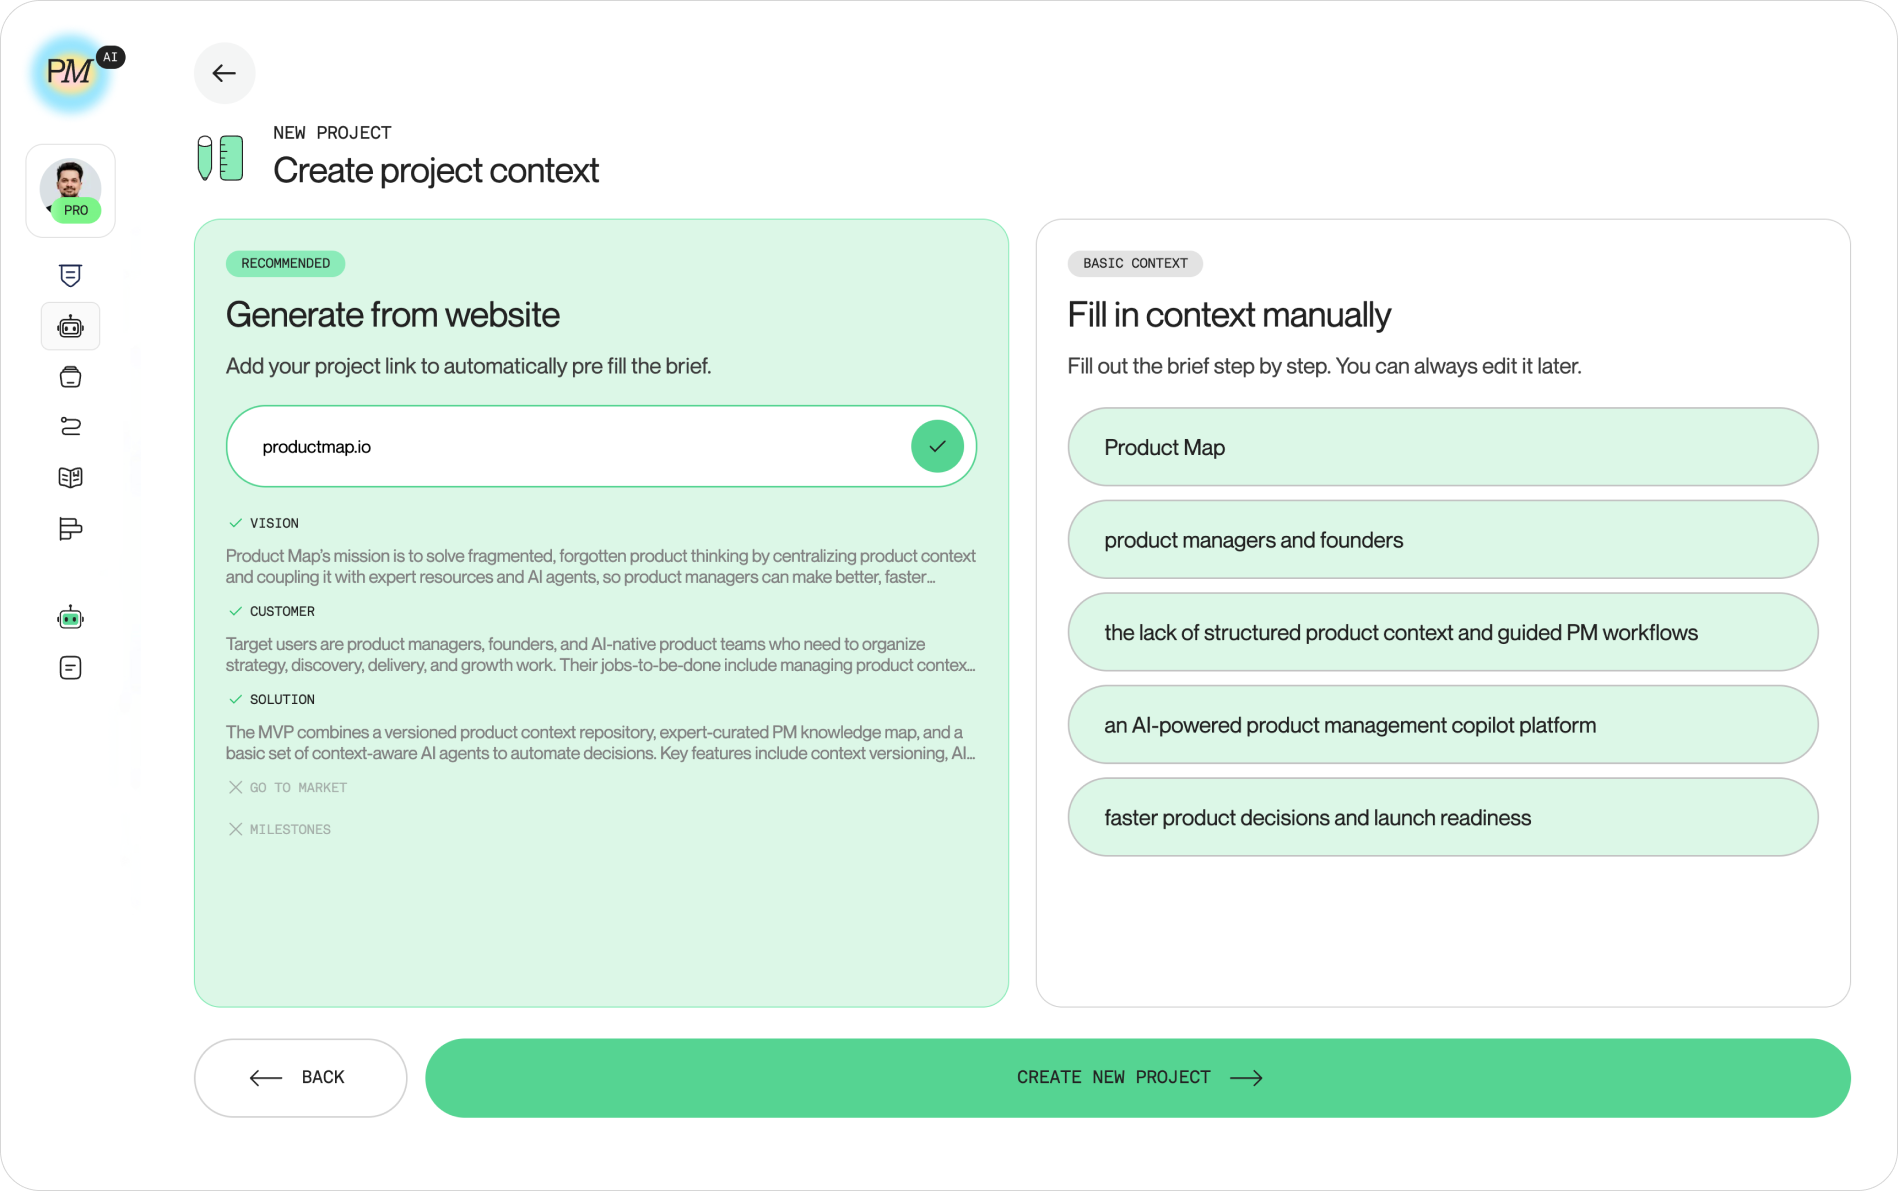
Creating a project opens a two-column choice: generate context from a website, or fill it in by hand. The website option calls out to your product's site and pulls a summary the way a person skimming the homepage would, positioning, audience, the problem it solves, then drops that into the brief for you to review.
Type your domain into the Generate from website field and confirm. Product Map fills the brief on the left with green checkmarks for what it found and greys out anything it couldn't infer. On the right, the same information appears as short editable fields: organization, target customers, product goal, pain point, and positive outcome. Read through both sides before you click Create new project.
Open the Bitbucket connection
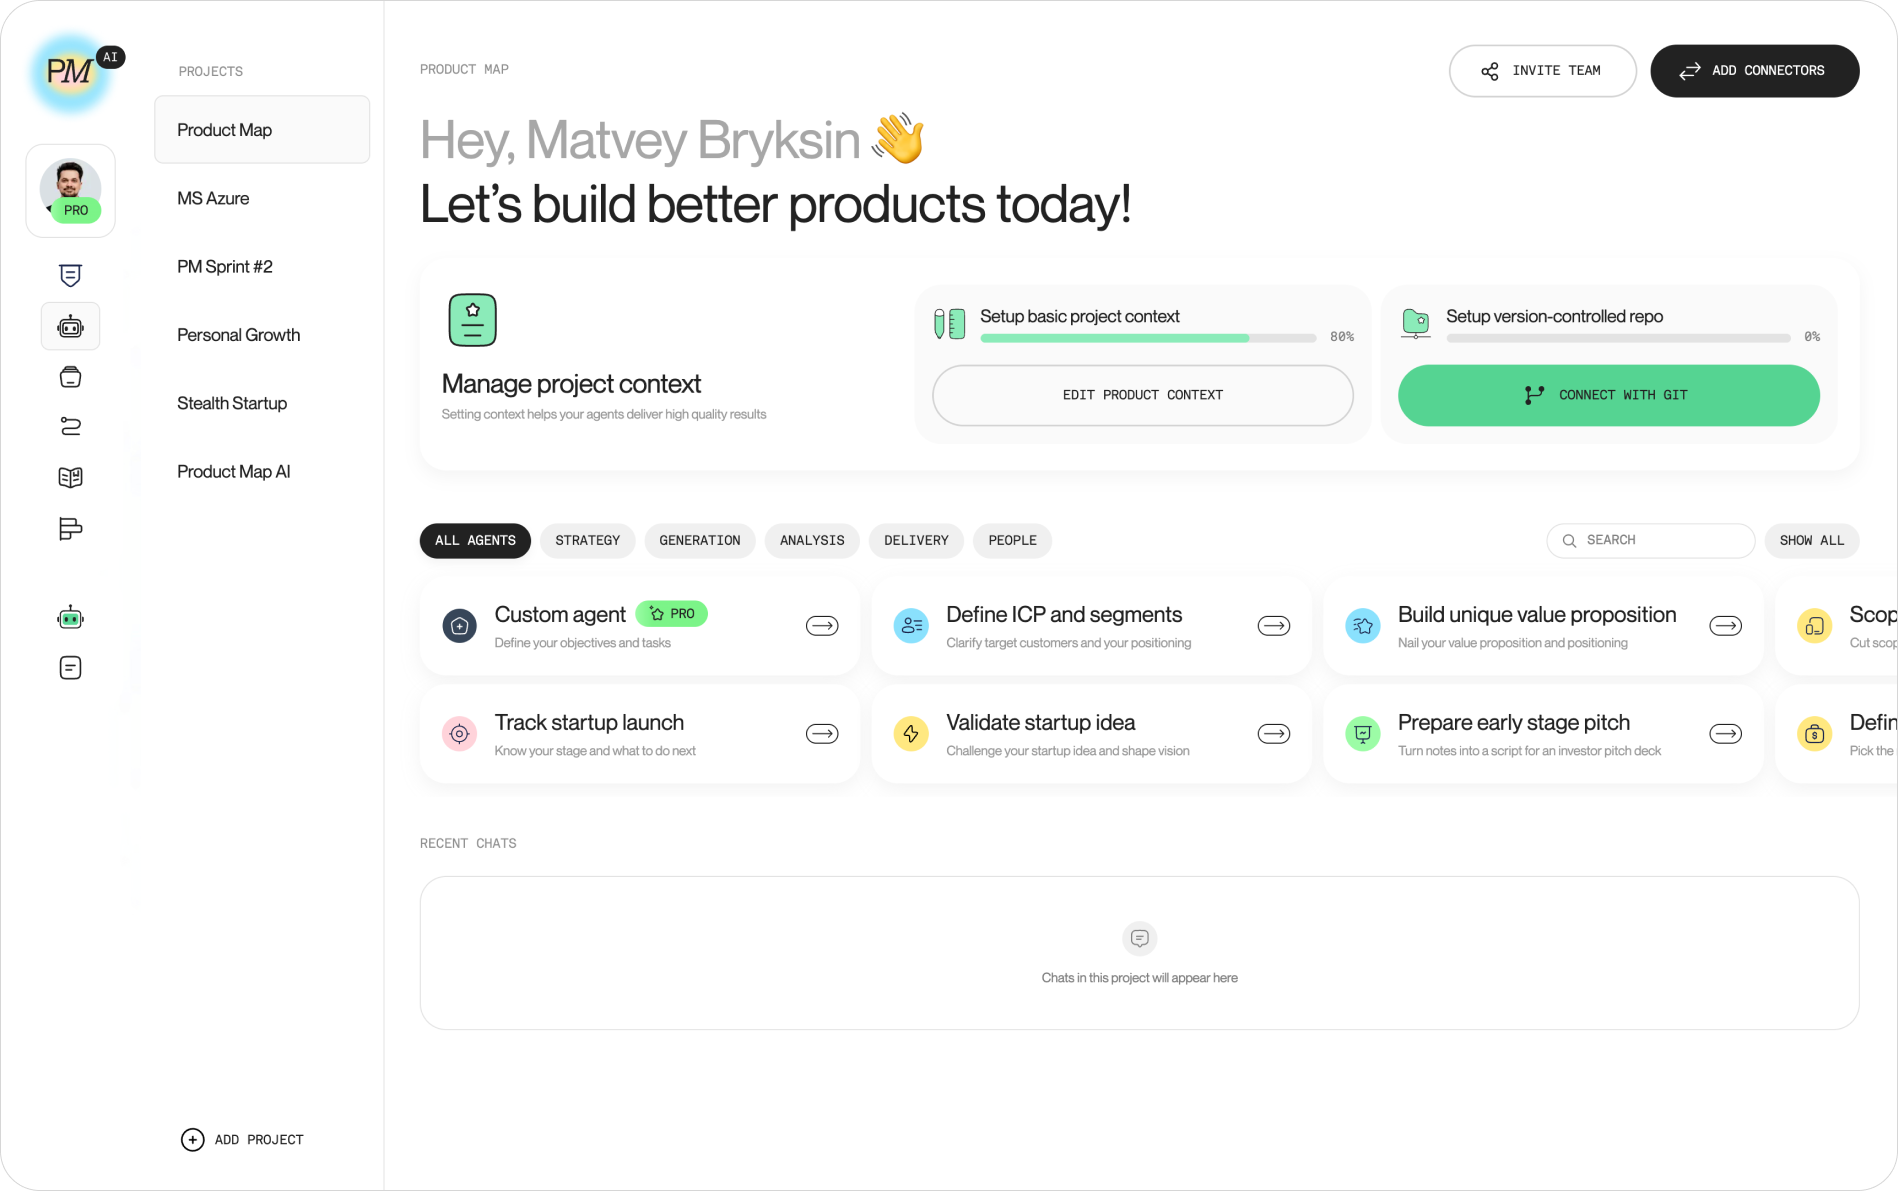
Your new project lands on a home screen with two progress trackers: Setup basic project context, already partway done from the step above, and Setup version-controlled repo, sitting at 0%. The second one is where the Bitbucket connection starts.
Click Connect with Git. The basic context bar doesn't need to hit 100% first; the two setups run independently of each other.
Create a Bitbucket repository
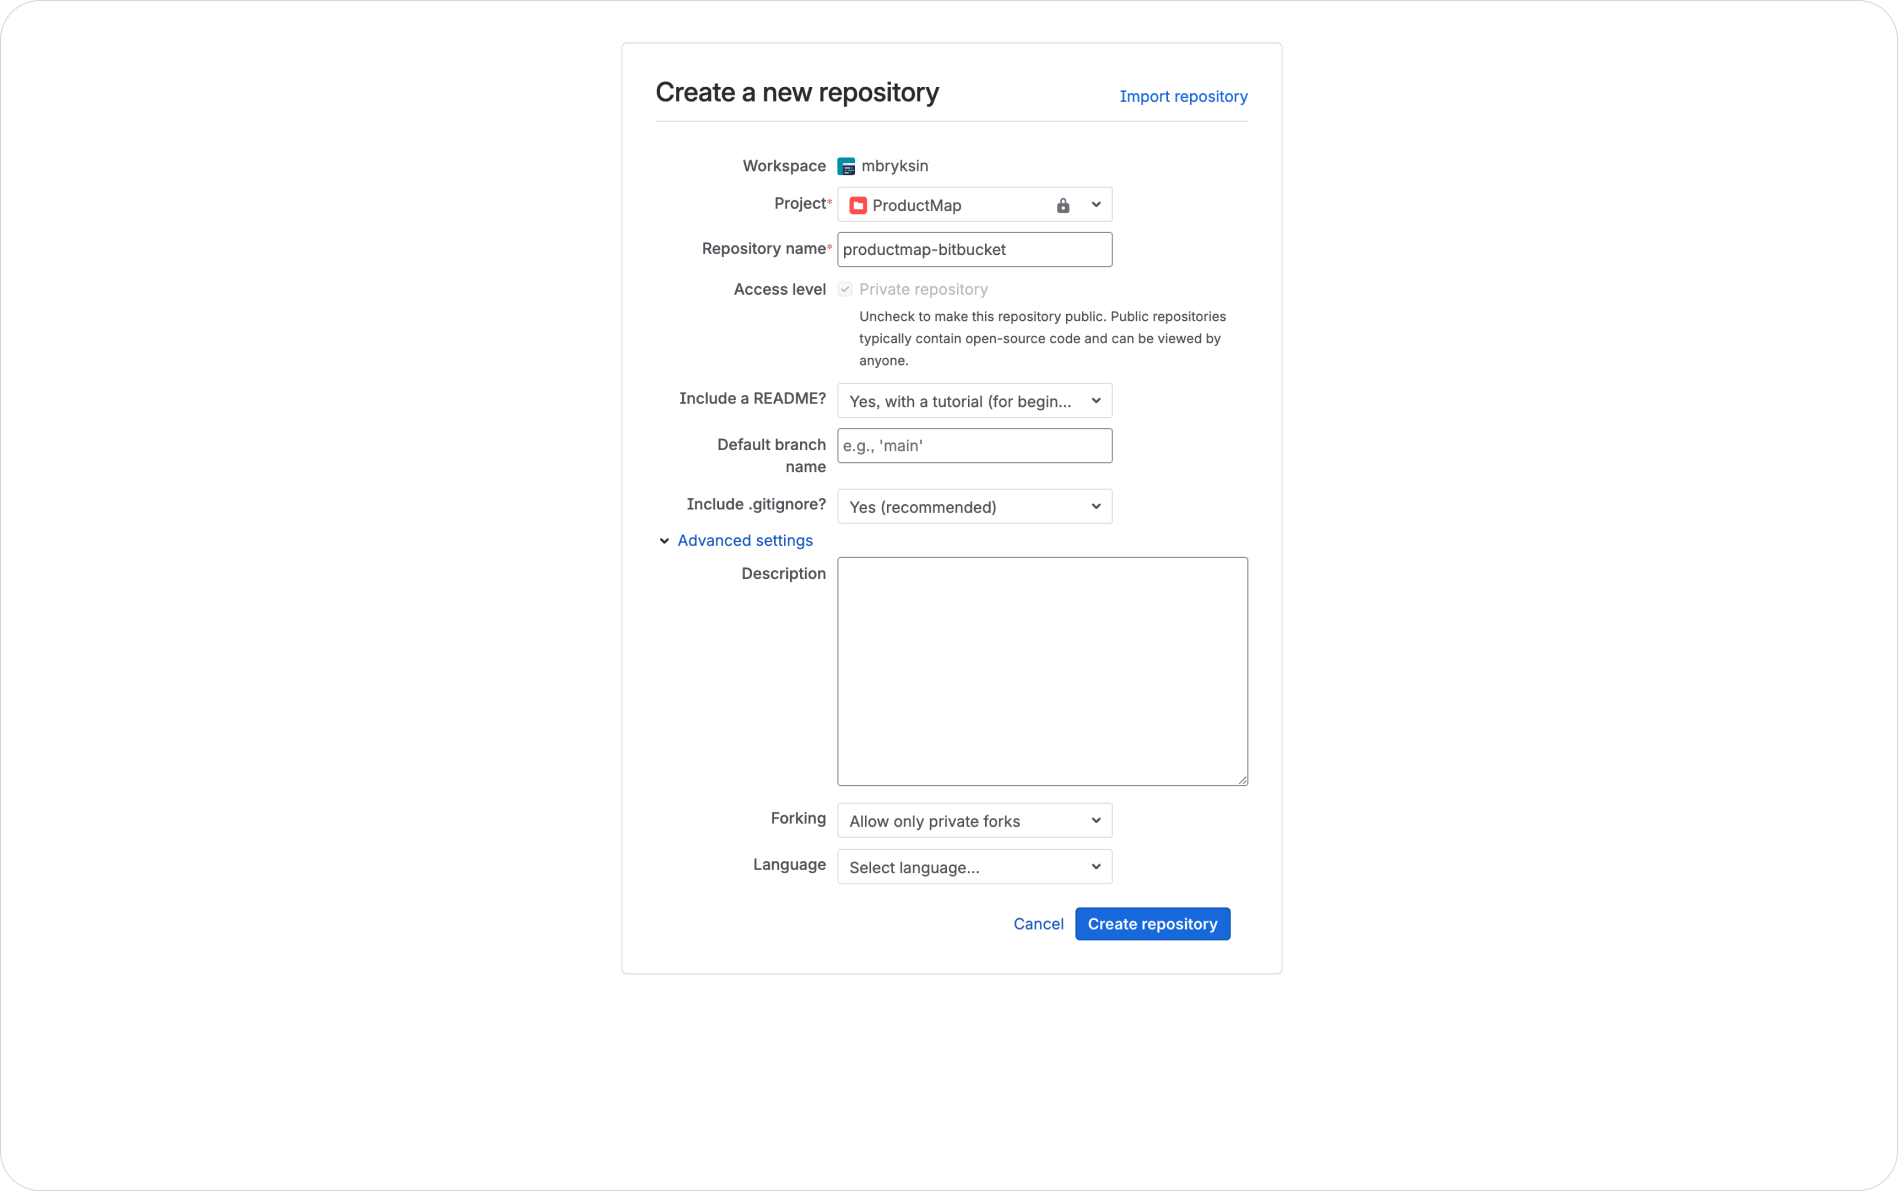
Product Map works against a repository you already have; it doesn't create one for you. If you don't have a repo yet, open Bitbucket and create one before you connect.
On the Create a new repository screen, pick your workspace and project, name the repository after the product, and keep it private. Tick Include a README or Include .gitignore so Bitbucket creates the default branch. An empty repository has no default branch, so the bot has nowhere to write the .productmap folder, and the first publish fails with an unknown-default-branch error. A README with one line is enough.
Select Bitbucket as your provider
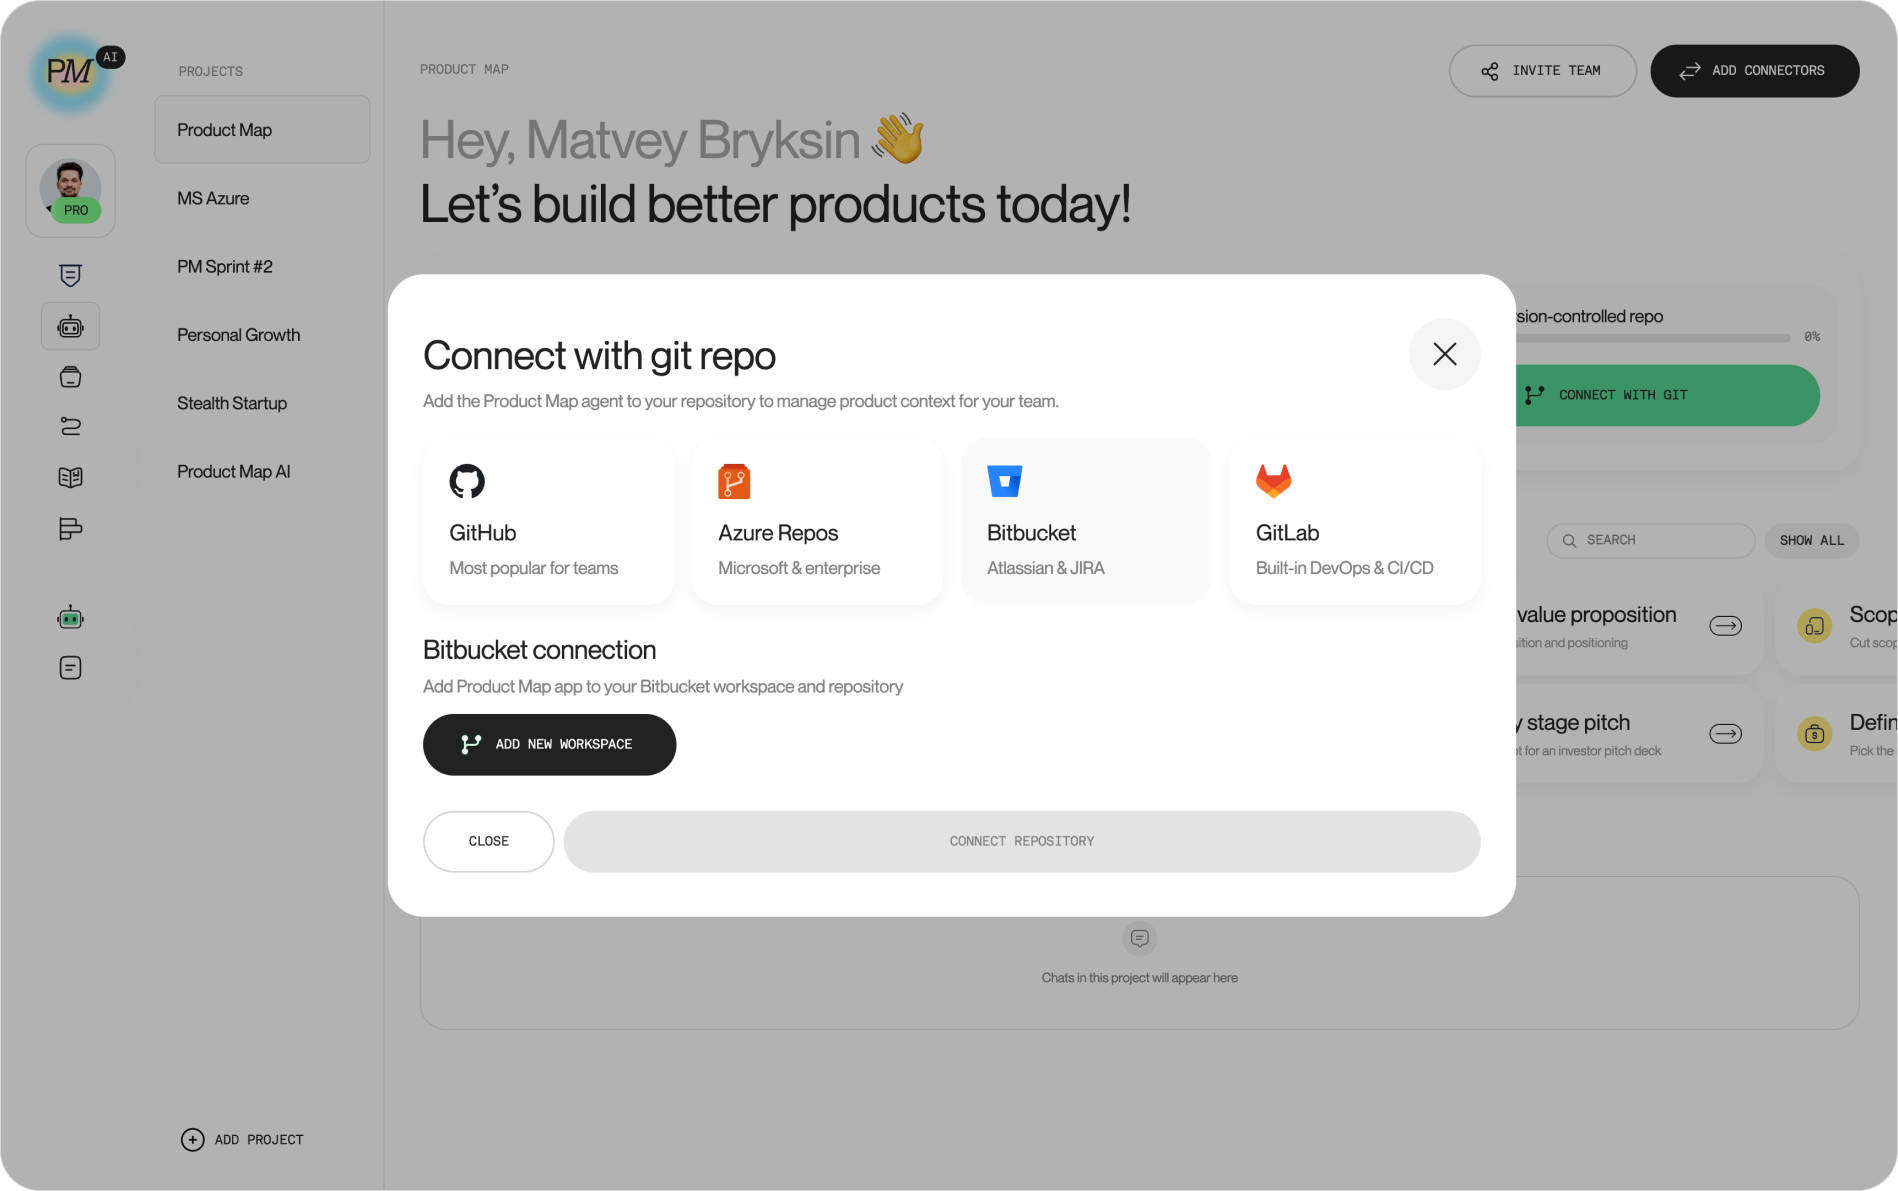
Back in Product Map, the Connect with git repo modal opens with four provider cards: GitHub, Azure Repos, Bitbucket, and GitLab. The Bitbucket card carries the tagline "Atlassian & JIRA."
Select Bitbucket. The section below the cards changes to Bitbucket connection, explaining that the Product Map bot gets added to your Bitbucket workspace and one repository inside it. The only button at this point is Add new workspace.
Authorize the Product Map app on Bitbucket
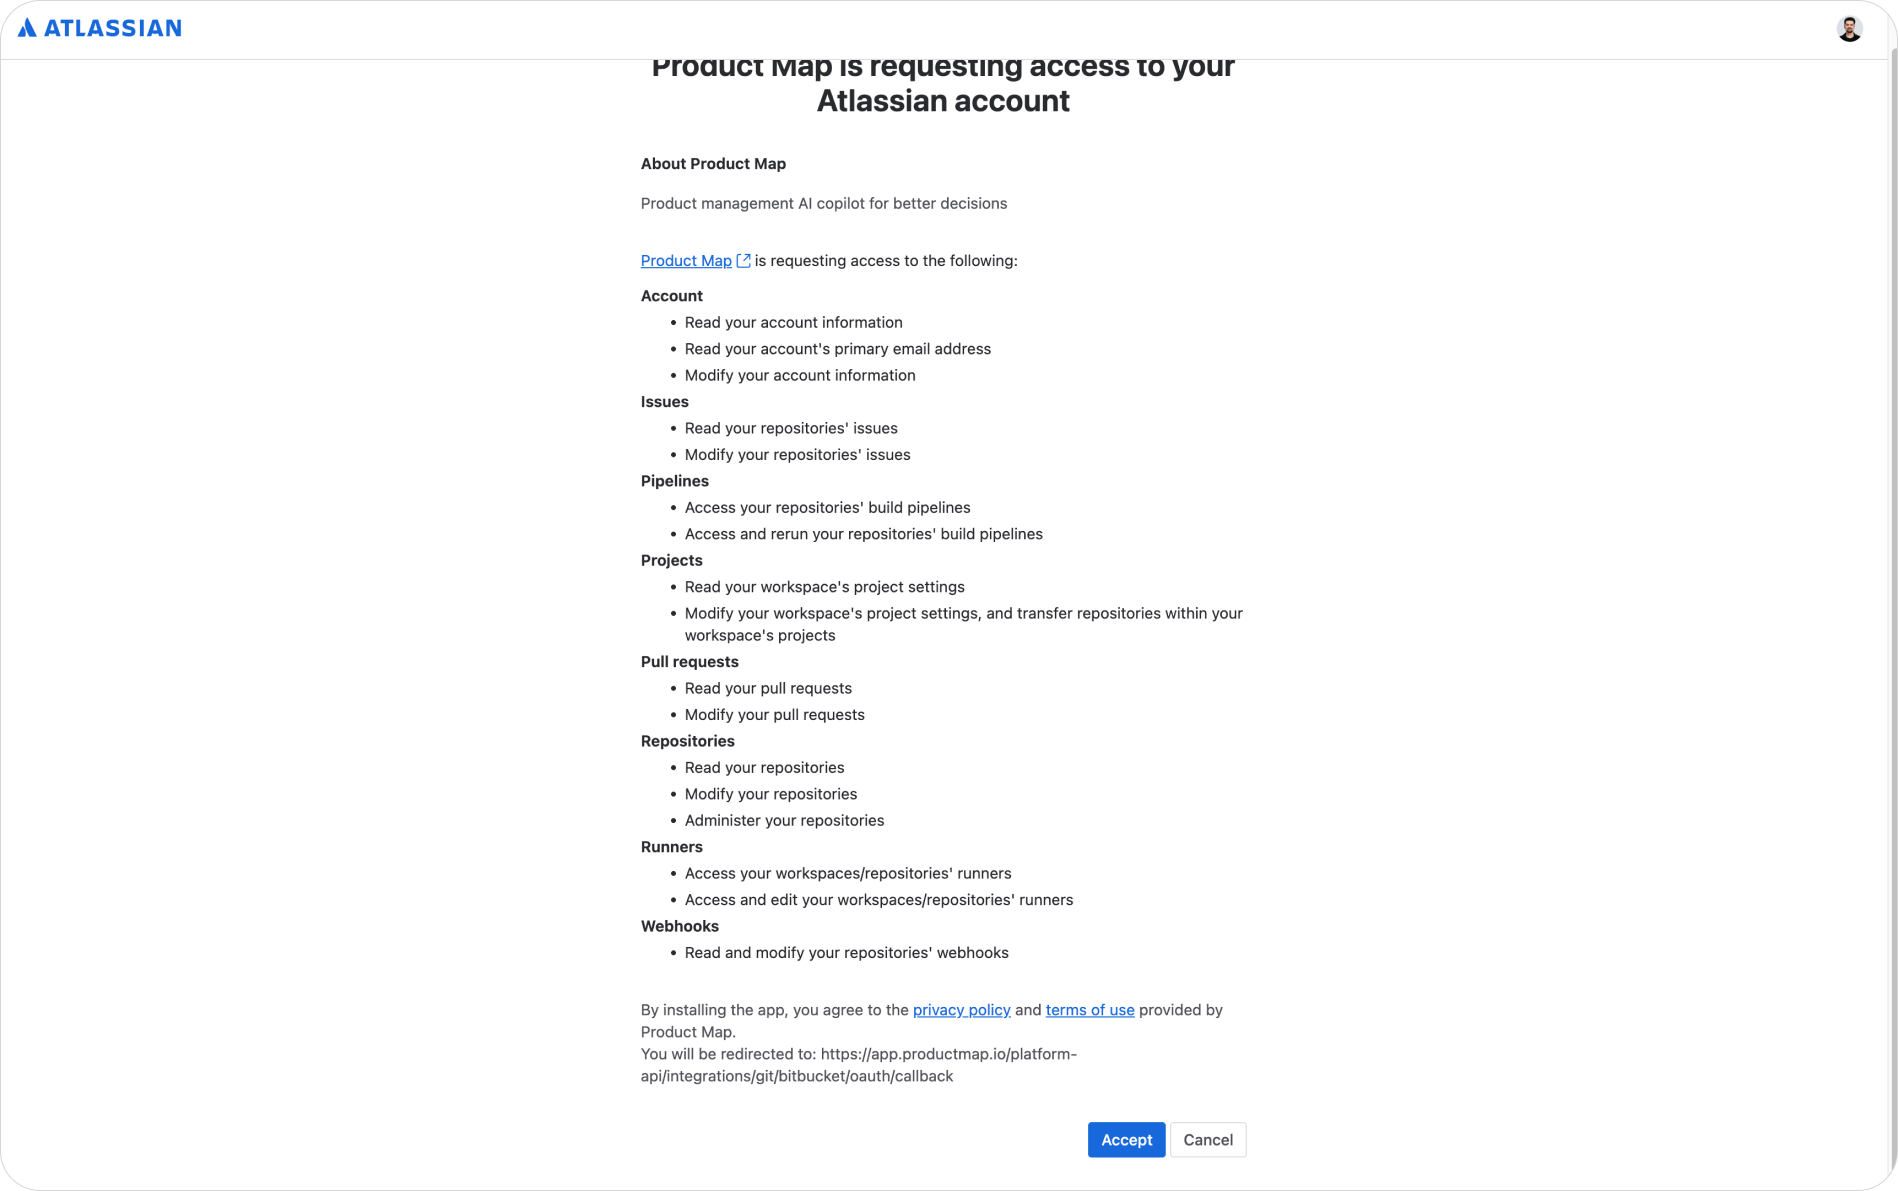
Clicking Add new workspace leaves Product Map and opens Bitbucket's authorization page in the same tab. It lists the account you're signed in with and the access the Product Map app requests on your repositories: issues, pipelines, projects, pull requests, repositories, runners, and webhooks. Check the account name before you approve. The app can only see the workspaces this account can reach.
Grant access and Bitbucket redirects you back to the same modal. No tokens to copy, no app password to paste.
Connect your repository
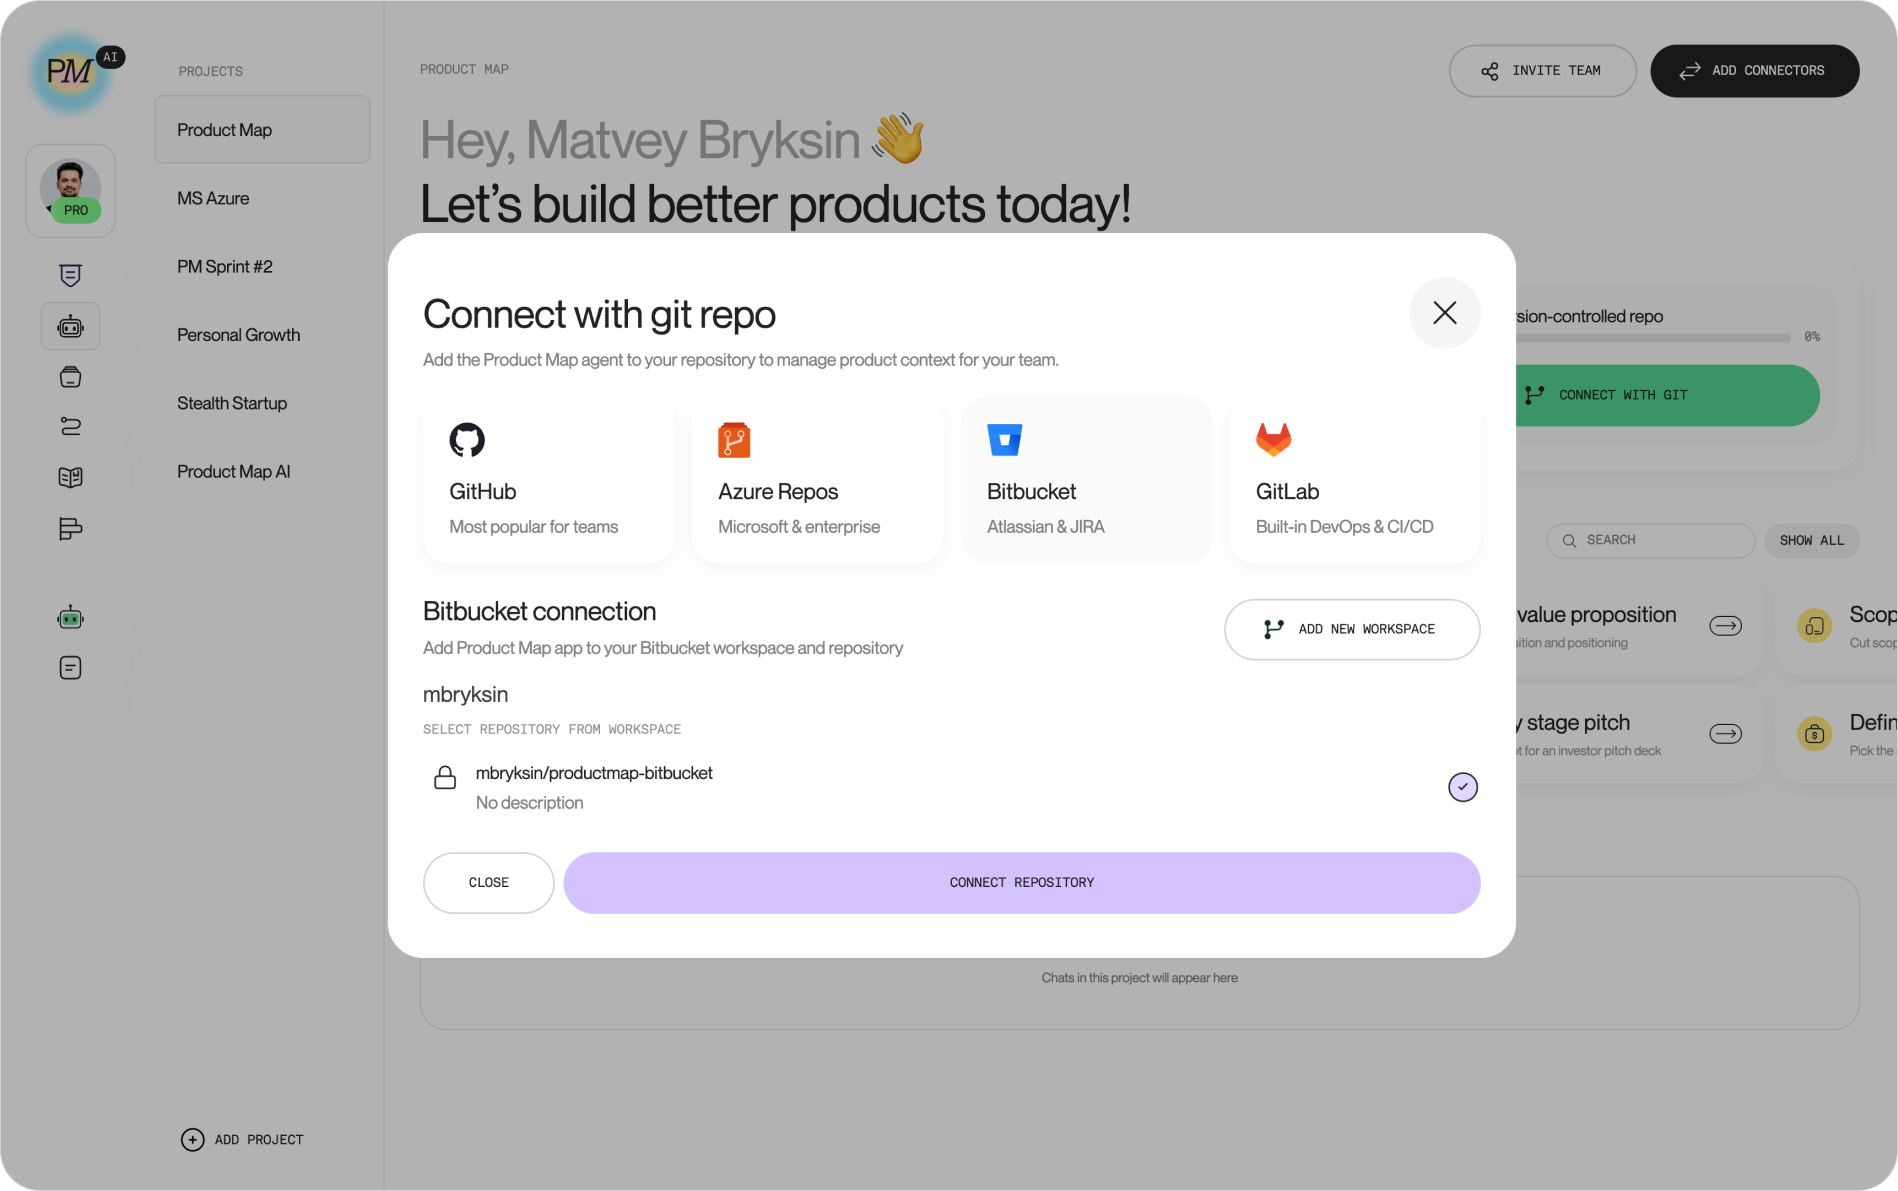
Back in the modal, your workspace appears as a heading, and every repository the app can see lists underneath it with a radio button. Repositories already linked to another Product Map project carry a Connected badge and can't be picked twice.
Choose the repository that will hold this product's context and click Connect repository. Two toasts follow: one confirming the link, one confirming the first context publish was requested. The project page button reads Bitbucket Connected, and the knowledge base panel shows the .productmap folder with numbered domain folders and starter files like onepager.md.
2. Set up connections with Jira and Confluence
The second connection brings Jira and Confluence into chat. One connector, one authorization, both products.
Open the Connectors catalog
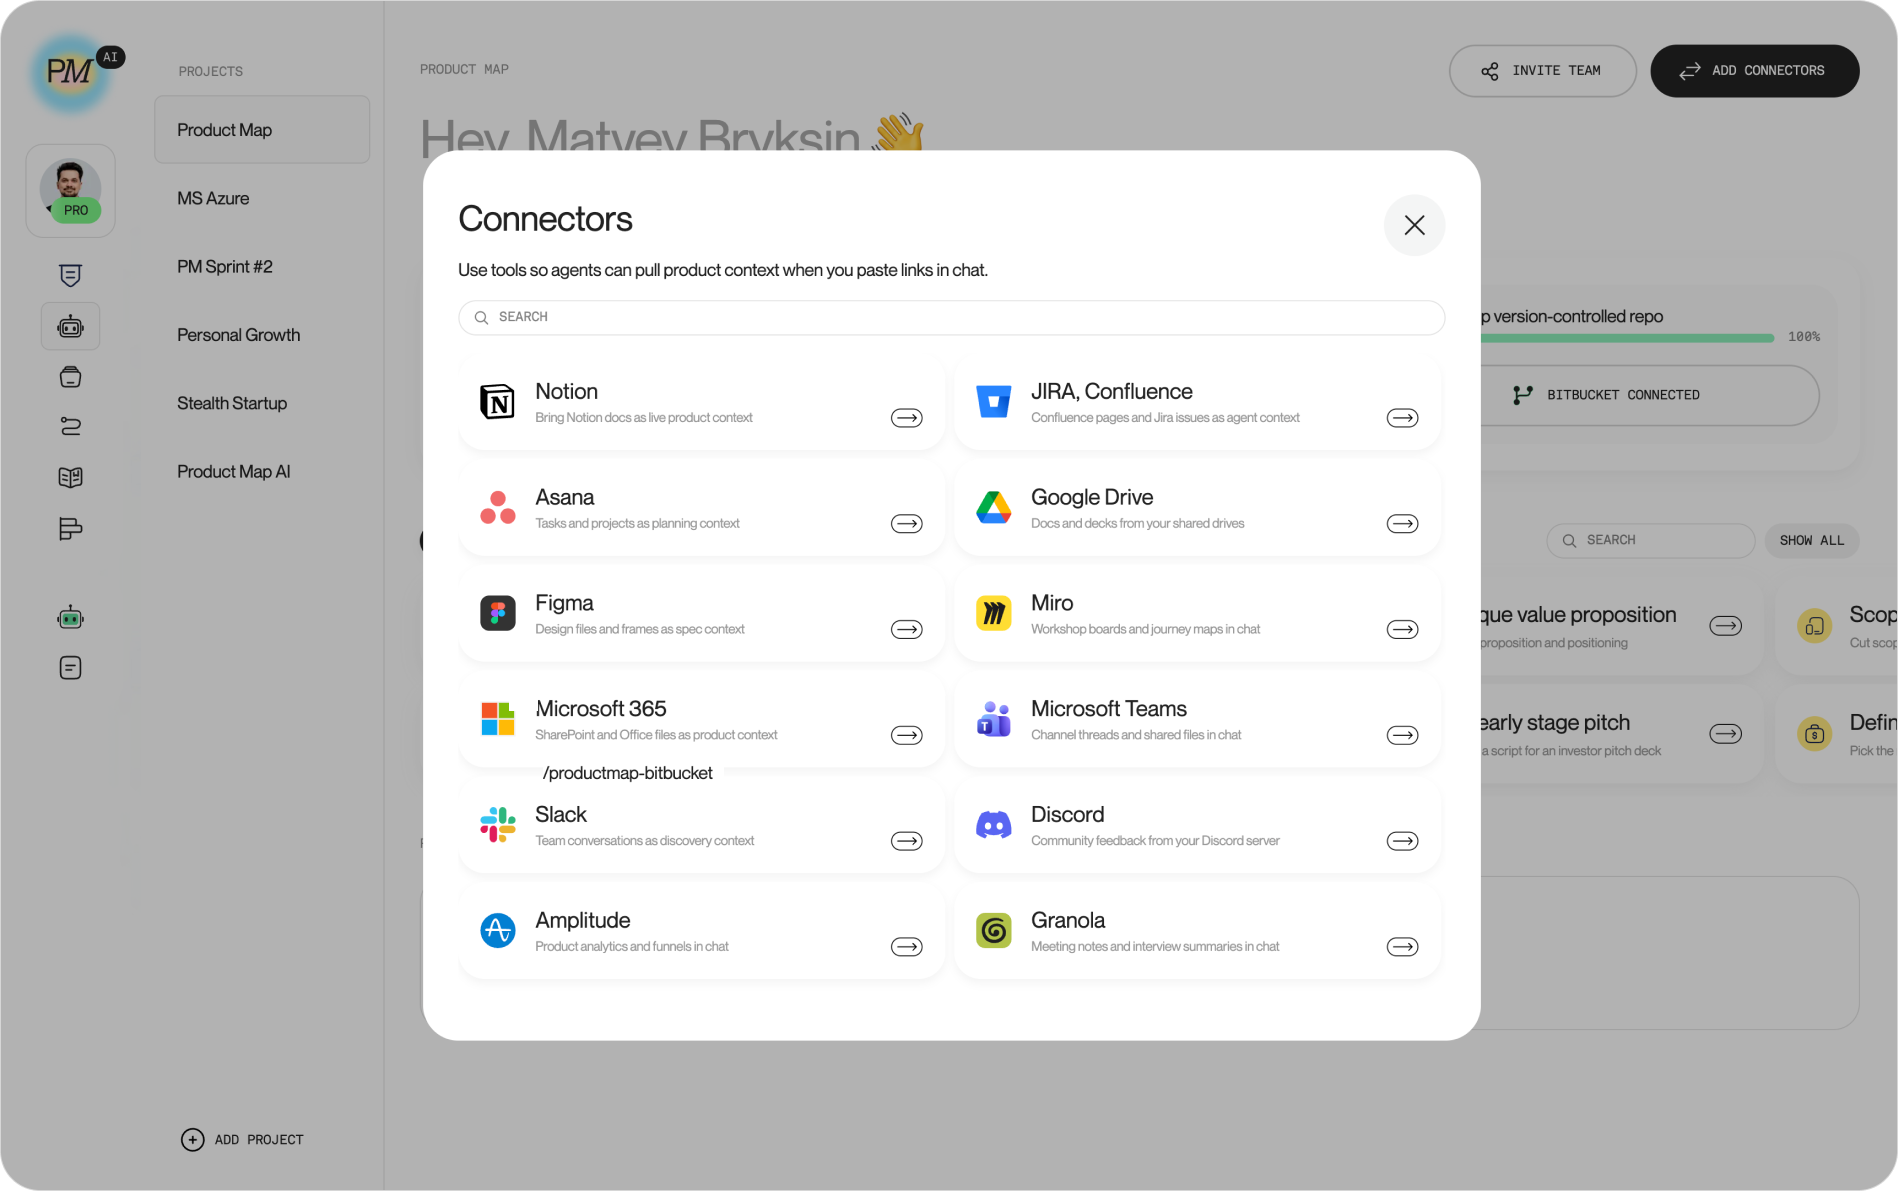
On the project page, click Add connectors in the header. The Connectors modal lists every source an agent can pull context from when you paste a link in chat: Notion, Asana, Figma, Miro, Microsoft 365, Teams, Slack, and a card named JIRA, Confluence. The same catalog sits inside any chat, under the Tools dropdown in the composer.
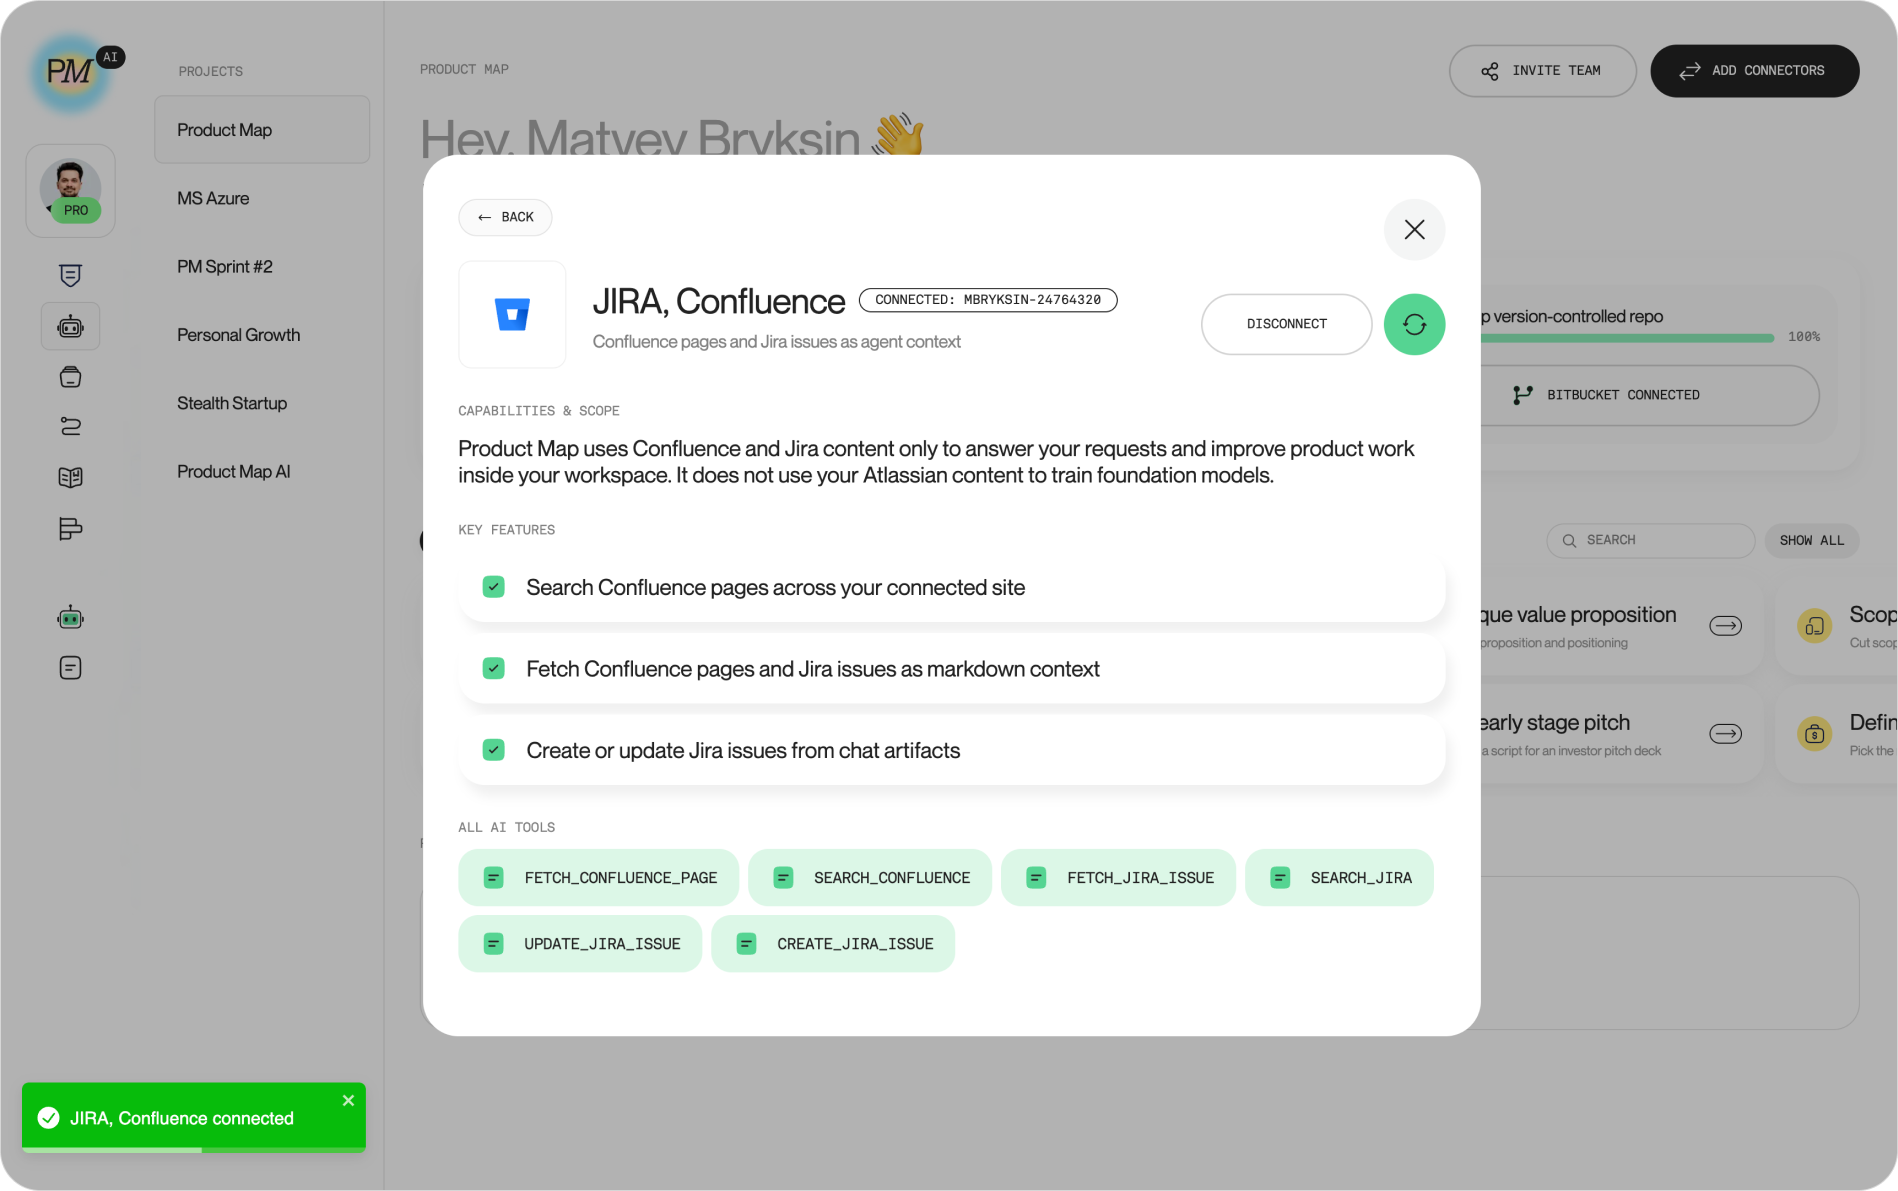
Open the JIRA, Confluence card. The detail view lists three capabilities: search Confluence pages across the connected site, fetch Confluence pages and Jira issues as Markdown context, and create or update Jira issues from chat artifacts.
Authorize on Atlassian
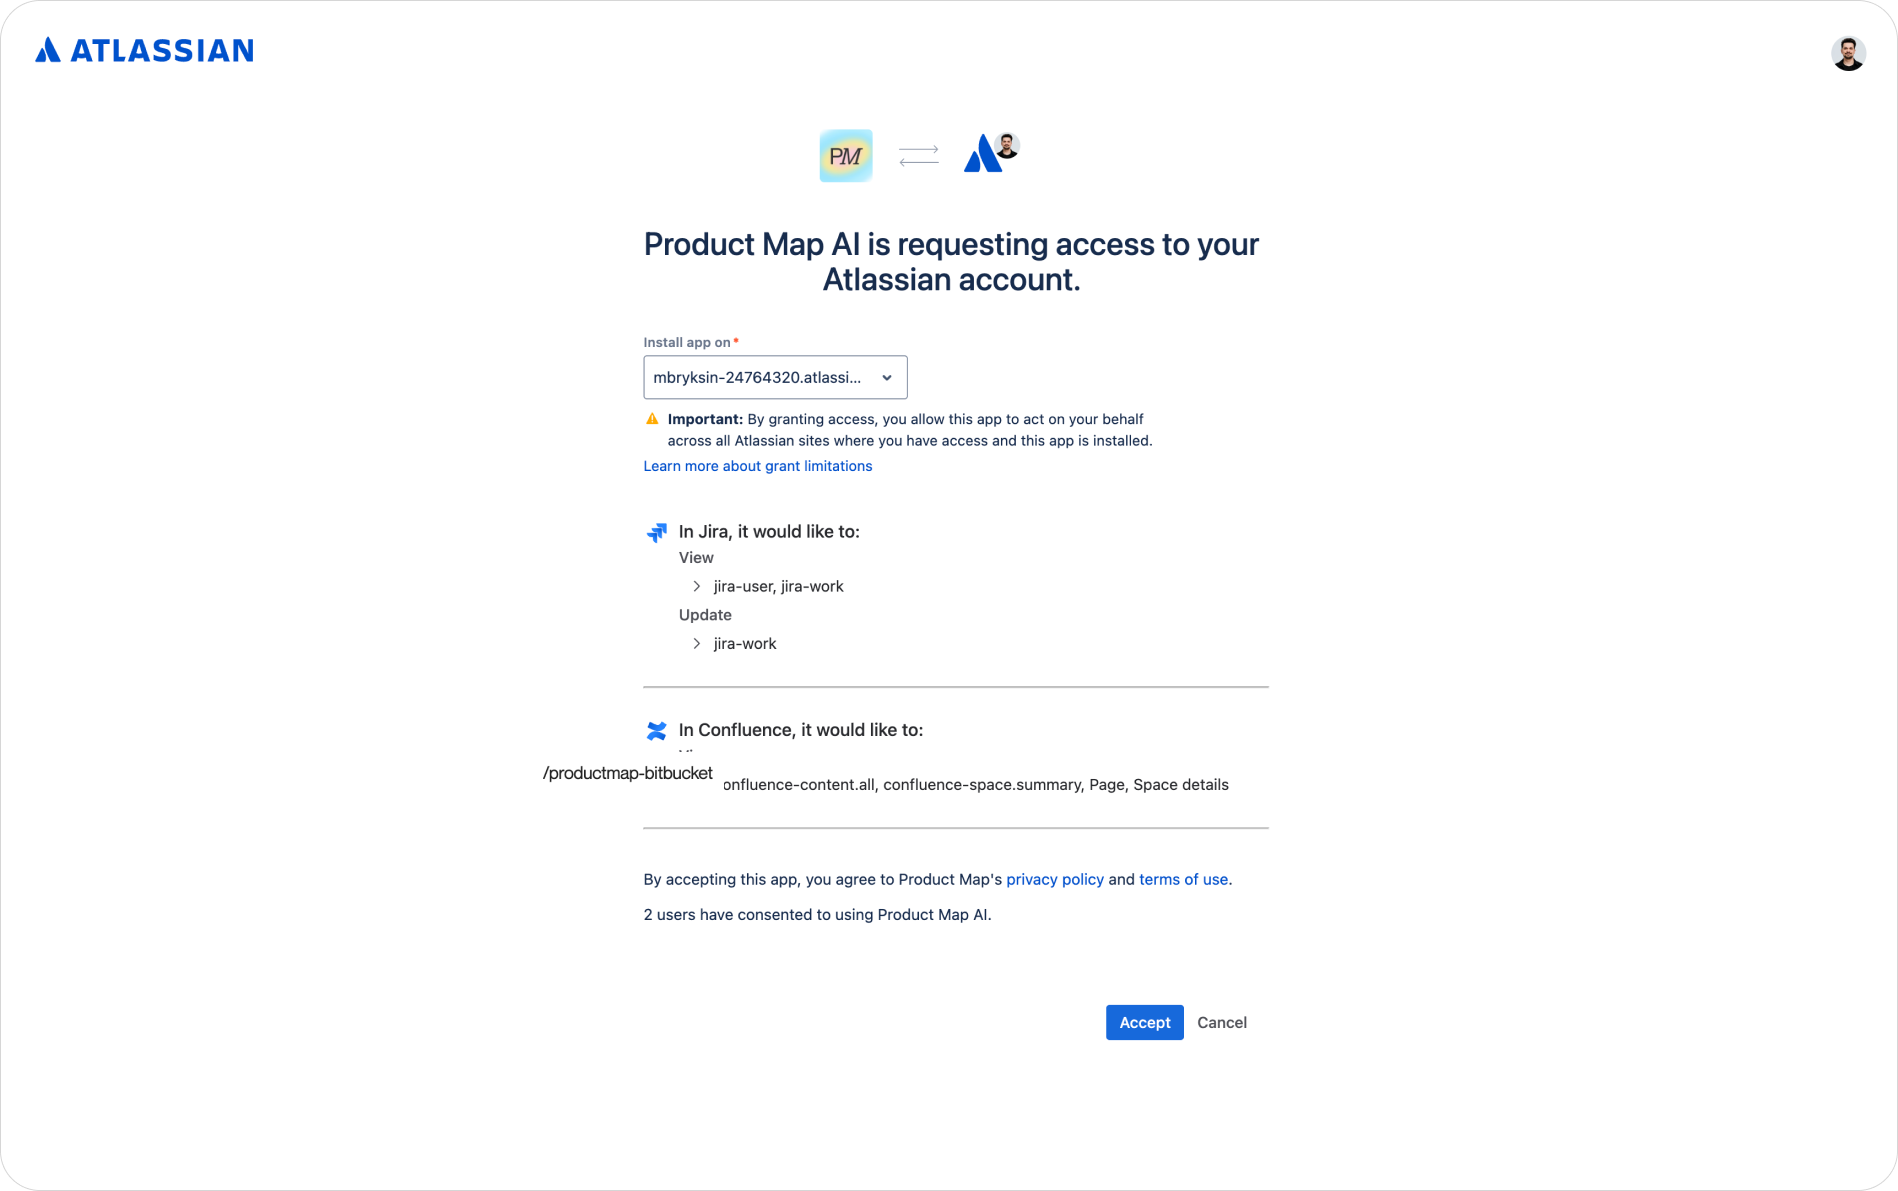
Click Install connection. You land on Atlassian's consent screen for Product Map AI, which names the site the app will access and the scopes it asks for. In Jira: view and update work items. In Confluence: read page and space content. Only a project admin in Product Map can complete this step or disconnect it later.
Approve, and Atlassian returns you to the Connectors modal. One catch: if your Atlassian account can reach more than one site, Product Map connects the first one it's granted. Sign in with the account whose default site holds the Confluence space and Jira project you care about.
Confirm the connection
Back in the Connectors modal, a toast reads JIRA, Confluence connected. The card now shows a Connected badge with your Atlassian site name, plus Disconnect and a sync button for later. The detail view also states the data rule: your Atlassian content is used only to answer your requests, never to train foundation models.
Below the capabilities list sits the full tool set the connector enables: FETCH_CONFLUENCE_PAGE, SEARCH_CONFLUENCE, FETCH_JIRA_ISSUE, SEARCH_JIRA, UPDATE_JIRA_ISSUE, and CREATE_JIRA_ISSUE.
3. Create a PRD from a Confluence page
Both connections are live. This phase exercises the connector fetch and the repository write gate before you touch Jira.
Open the PRD agent and paste the Confluence link
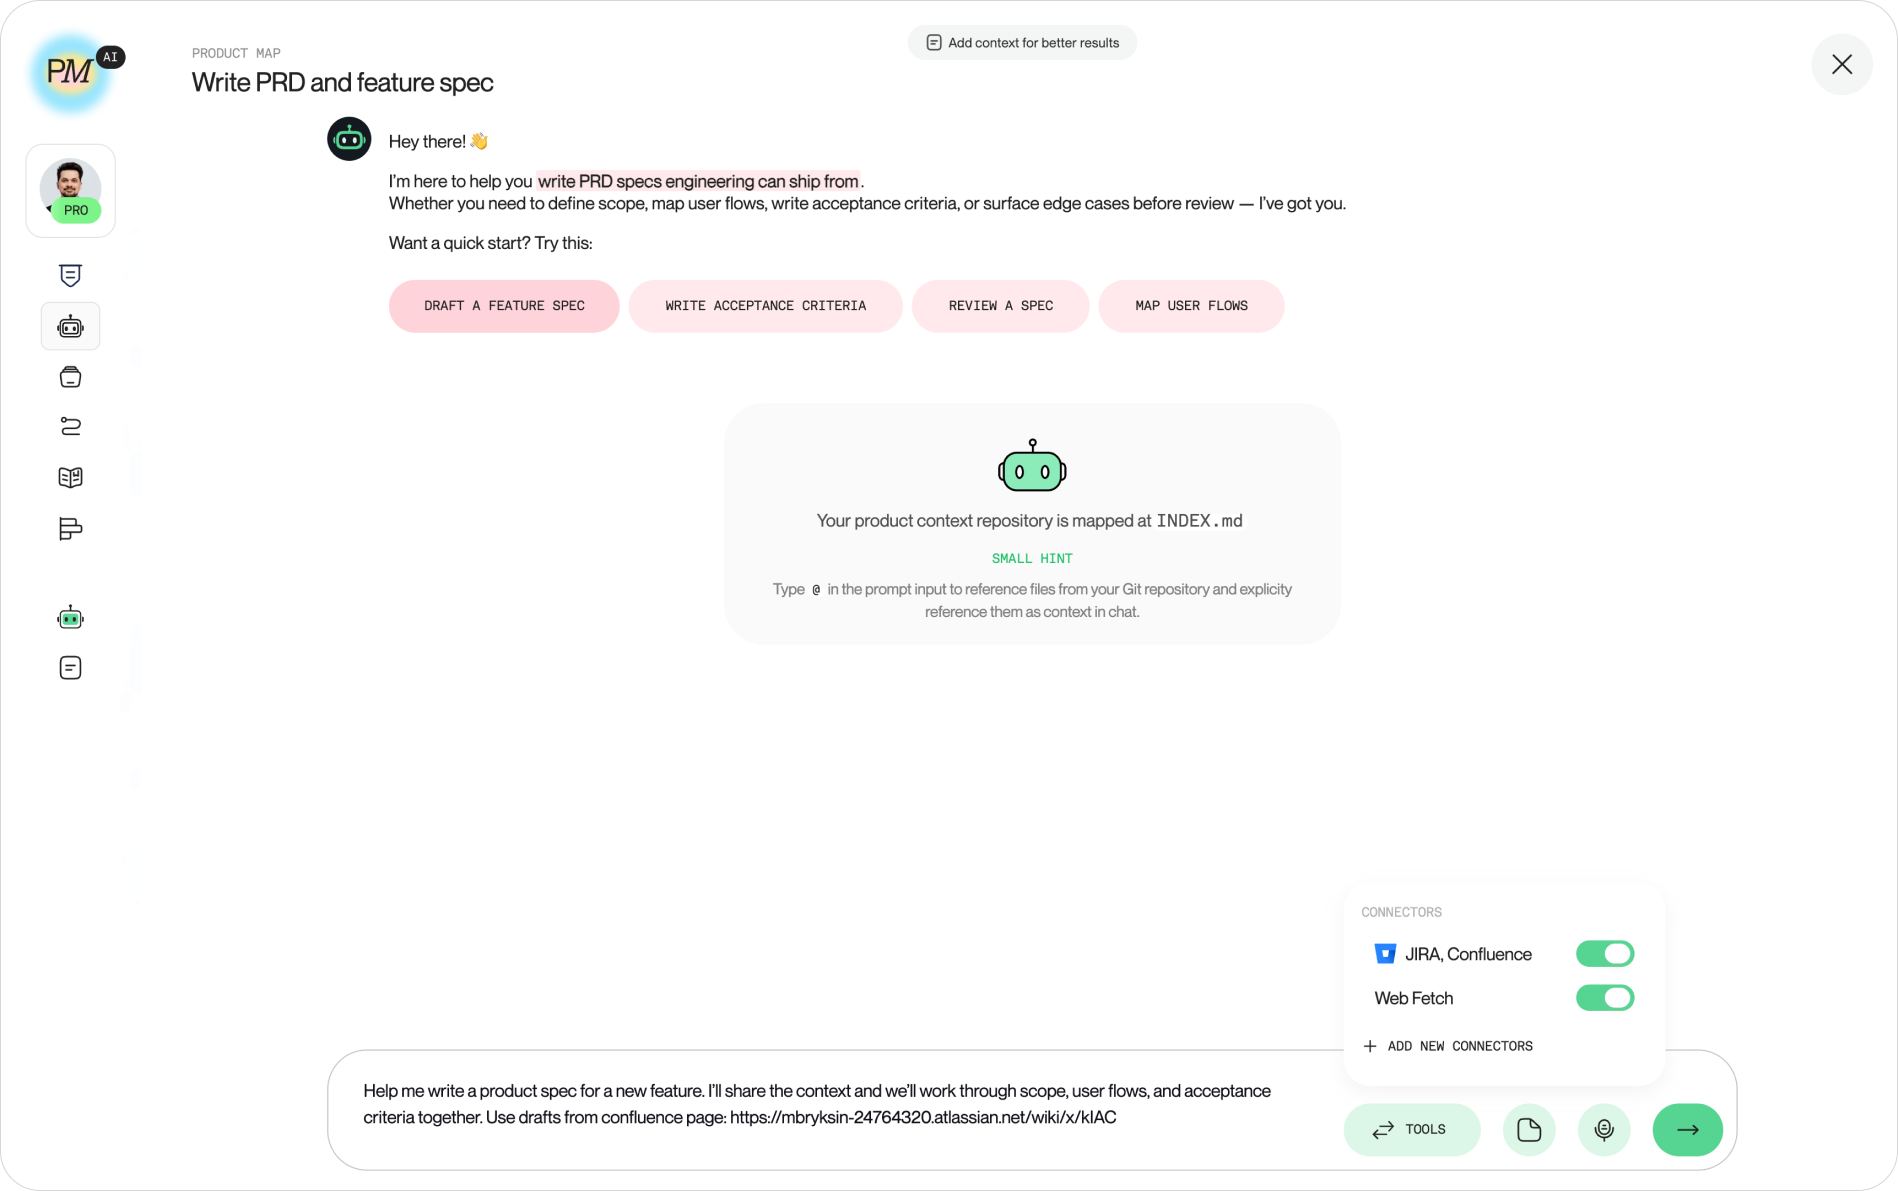
Open Write PRD and feature spec from the agent list, or any delivery agent in the project. Paste the URL of a Confluence page holding a product requirement and ask the agent to draft a spec from it. A Confluence link in the message switches the JIRA, Confluence tool on for that turn.
Open the Connectors menu in the composer and confirm JIRA, Confluence and Web Fetch are toggled on. Product Map fetches the page before the model starts, converts it to Markdown, and hands it to the agent as a marked external source.
Review the drafted spec
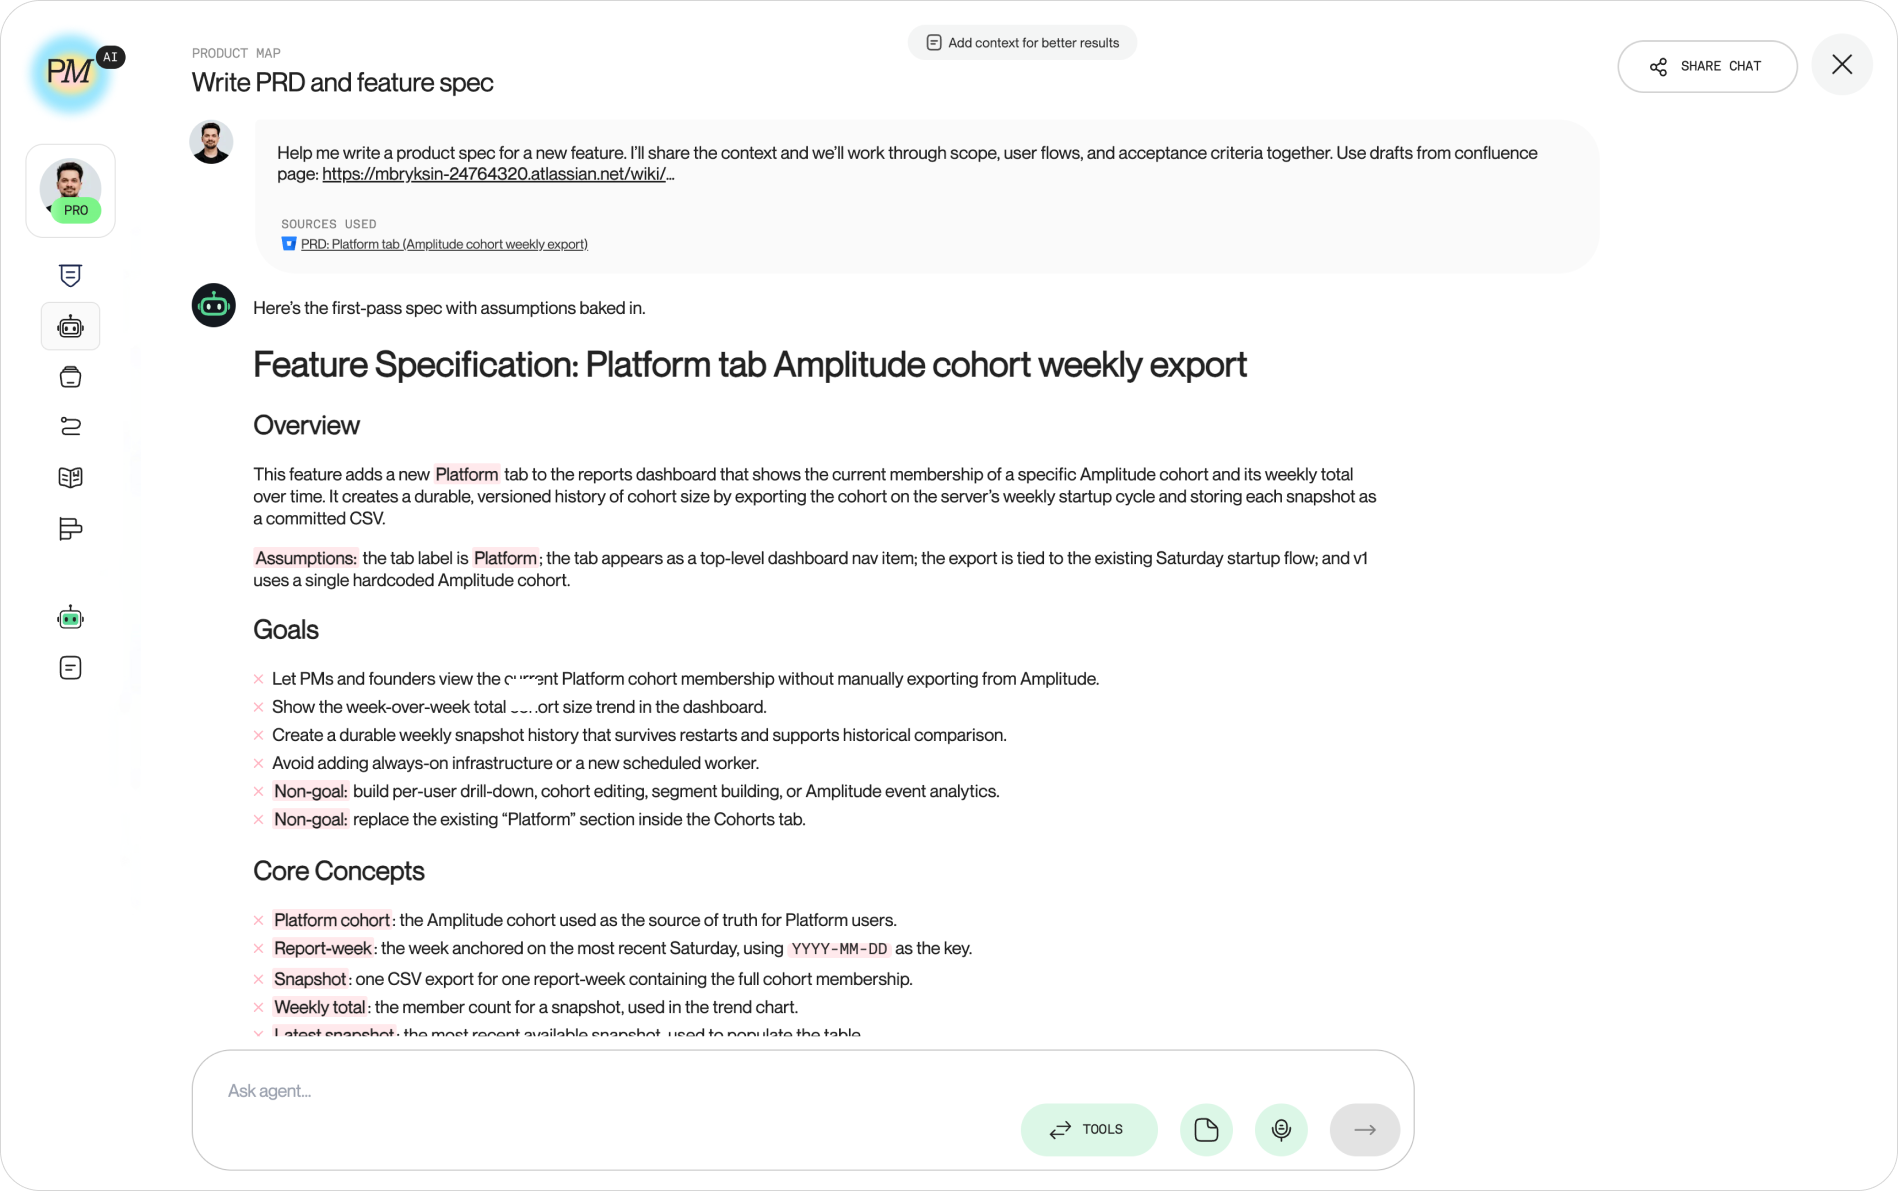
The agent returns a structured first-pass spec: overview, goals, non-goals, and core concepts pulled from the Confluence draft. Under the reply sits a Sources used row with a chip carrying the page title. If the chip reads "failed," the page is invisible to the account you authorized. Share the space with that account, or reconnect with the right one.
Read the spec in chat before you move on. This is the point where you correct scope, fill gaps, or ask the agent to tighten acceptance criteria while the Confluence source is still attached.
4. Create a Jira ticket and push context to Bitbucket
The spec is ready. This phase files the requirement in Jira and commits the PRD and backlog updates to Bitbucket in one pass.
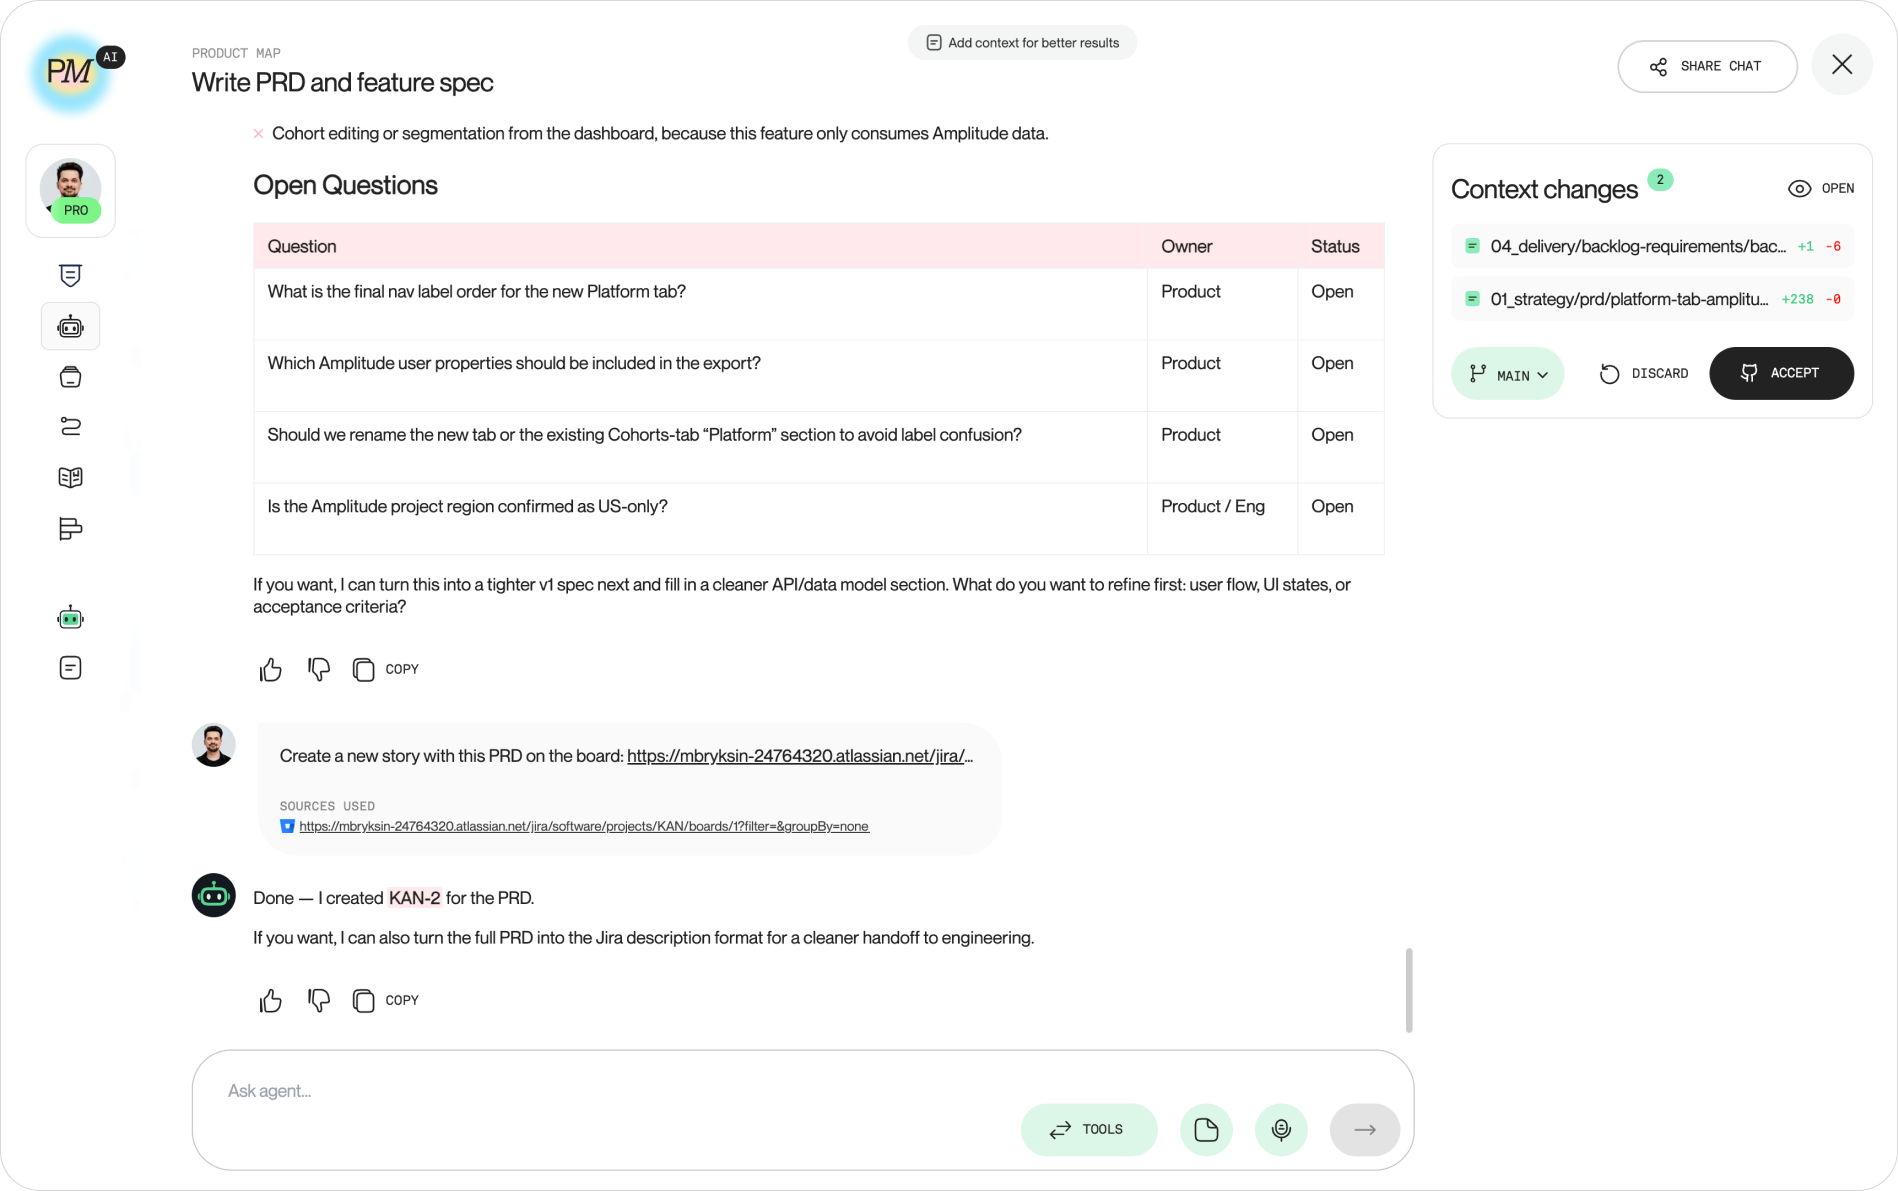
Create the ticket and accept context changes
In the next message, ask the agent to create a Jira story from the PRD and paste the link to your board. A board URL carries no issue key, so the agent reads the project key from the URL and calls the create tool directly.
At the same time, the agent proposes repository changes. The Context changes panel on the right shows two pending files: an updated backlog.md and a new PRD under .productmap. Next to Discard and Accept sits a branch selector. Push to main commits straight to the default branch, which suits a solo project. Open Pull Request creates a branch and a PR instead, the right setting once a second person writes to the repo. Nothing touches Bitbucket until you click Accept, and only project admins can.
Confirm the commit in Bitbucket
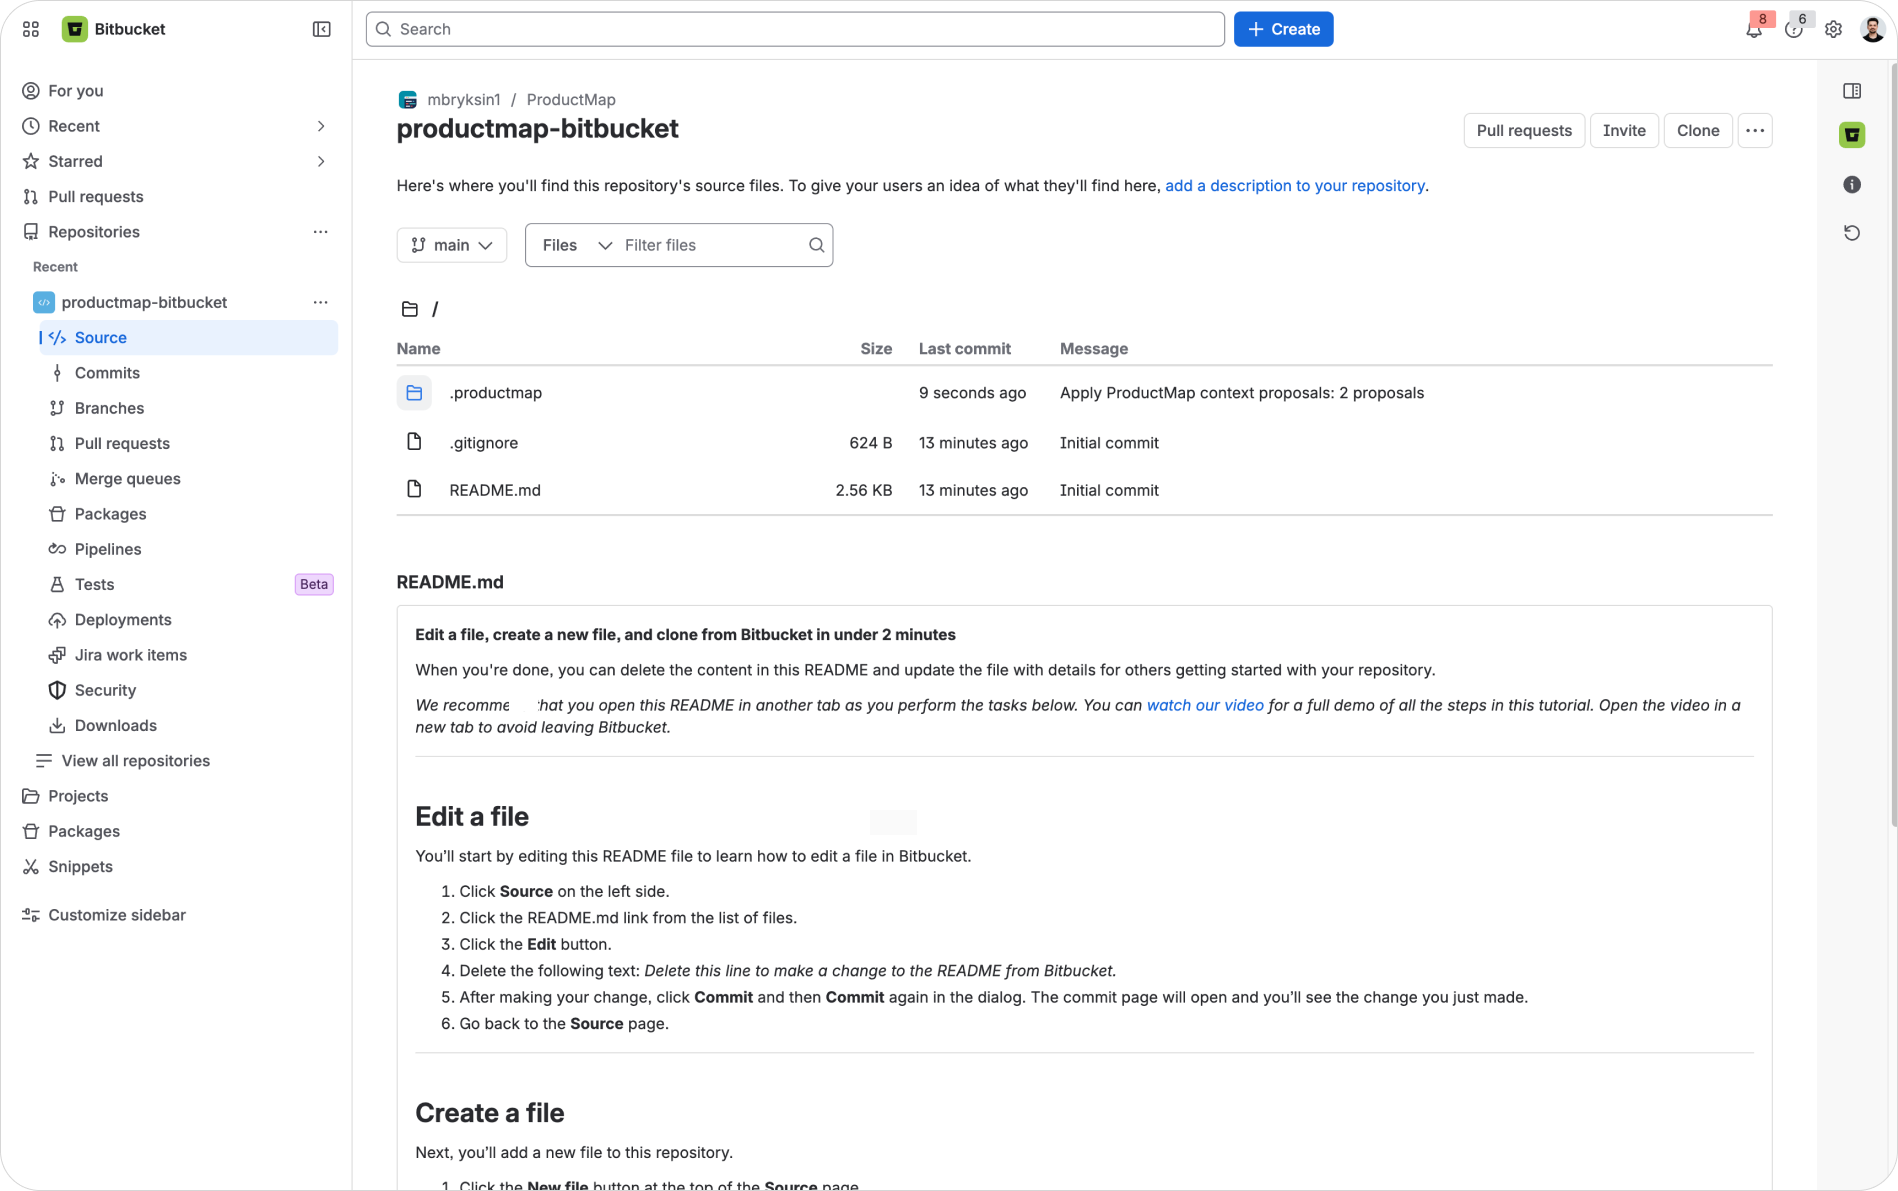
Click Accept. Open the repository on bitbucket.org and the .productmap folder is there, committed by the Product Map bot with a message like "Apply ProductMap context proposals." The backlog and PRD now live in Git alongside your code, and every agent in the project loads this requirement as Markdown files, not as API calls.
Open All Agents
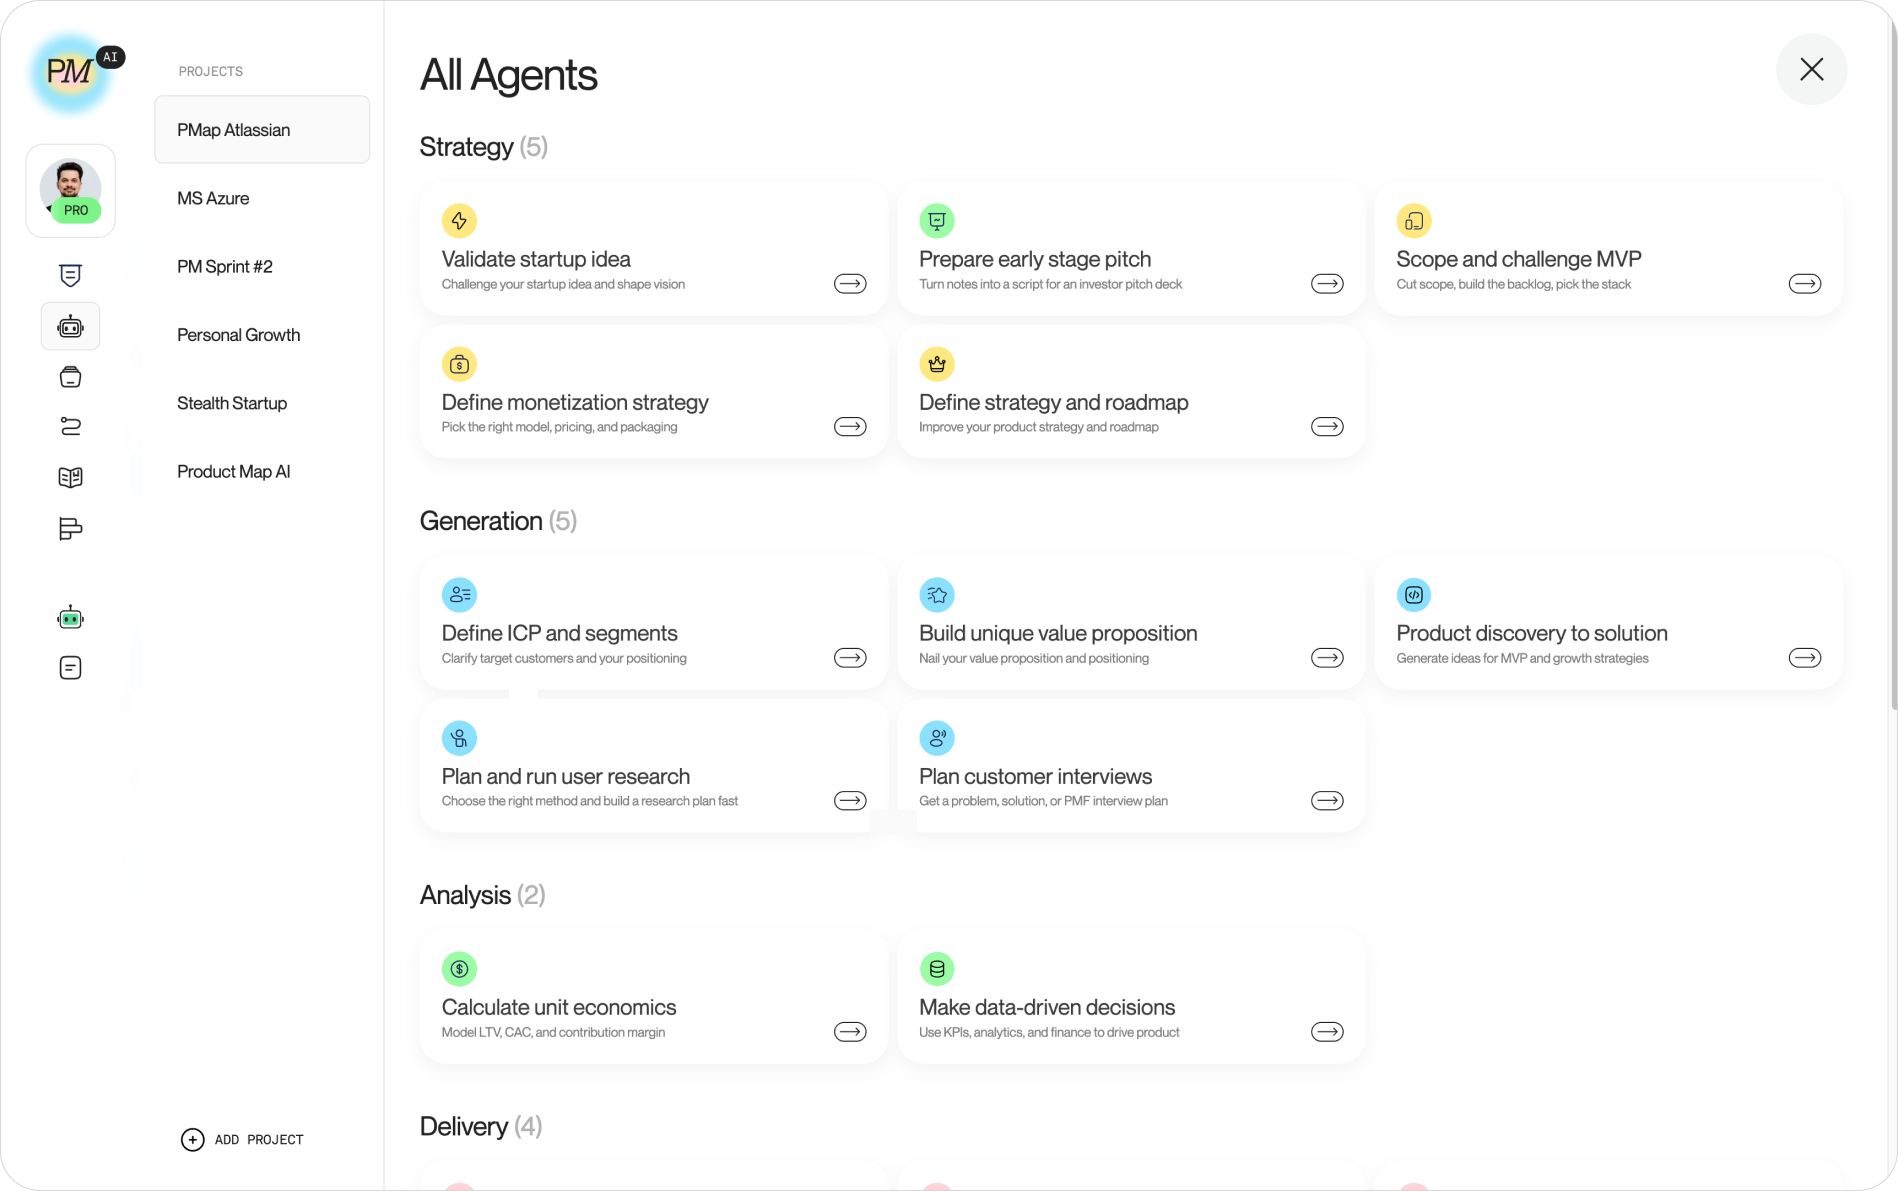
Back in Product Map, click through to All Agents to see the full catalog grouped by category: Strategy, Generation, Analysis, Delivery, and People. Each card names a specific task instead of a vague capability, so picking one reads closer to assigning a ticket than prompting a chatbot. With Bitbucket, Jira, and Confluence all connected, every agent in this list reads from the same repository and can pull Atlassian links you paste in chat.
The question nobody answers: which copy is the truth
After that test the same requirement exists in two places: the Confluence page where it was written and the Markdown file the agent committed. Any team hits this inside a week, and few decide it on purpose.
Decide it now. The repository copy is the one agents read, so it has to be the one you keep current. Two workable rules:
- Confluence is the draft, the repo is the record. People write and comment in Confluence. When a page is ready, someone pastes the link, an agent proposes the file, a reviewer accepts it. Later page edits mean a second paste and a second diff.
- The repo is the draft too. Agents and PMs write Markdown in the repository, and Confluence holds only what non-product stakeholders need to see. Cleaner, and a harder cultural sell in an Atlassian shop.
Either works. What fails is the third option, where both copies drift and the agent grounds a Jira ticket in a PRD nobody has updated since June. The review gate exists so a person notices. Use it.
The same call applies to Jira write access. Agents can create and update issues, and that is a real capability with a real blast radius. Keep Accept and connector installs with project admins, switch to Open Pull Request mode once a second person is in the repo, and read the ticket the agent created before sharing the board.
Do the setup once per product
Fifteen screens, one product. Afterward the loop is short: write in Confluence, paste the link, accept the file, ask for the ticket. Each pass adds one reviewed Markdown file to a repository every agent on the team already reads. Two months of that and the .productmap folder in Bitbucket holds a better record of the product than any wiki space.